pdfaPilot Desktop
conversion PDF/A pour l'archivage à long terme manuel
L’archivage sur une certaine période de toutes les communications portant sur des sujets spécifiques constitue une exigence réglementaire dans bon nombre d’environnements. pdfaPilot vous permet de garantir l’archivage et la consultation longue durée de vos documents.
Vos documents et e-mails archivés pour la vie
Dans beaucoup d'environnements, obligation est faite d'archiver toute communication relative à des sujets spécifiques pour une certaine durée. Celle-ci peut varier fortement, allant de quelques années à plusieurs décennies.
Le format de prédilection pour l'archivage est défini dans la norme ISO PDF/A (PDF/Archivage). Cette norme ISO définit trois versions différentes de PDF/A, et callas pdfaPilot peut automatiquement convertir tous vos documents et e-mails dans la variante de PDF/A qui sert le mieux vos objectifs. Les informations supplémentaires sur le travail (métadonnées) sont entièrement prises en charge, et la solution est suffisamment configurable pour s'adapter à votre flux de travail, plutôt que l'inverse.
L'archivage des documents est une opération cruciale pour les flux de travail modernes. Aussi callas pdfaPilot a-t-il fait l'objet d'essais intensifs, destinés à vérifier sa conformité aux normes ISO, par exemple avec la suite de tests Isartor. Adobe Acrobat, le standard de fait, utilise exactement la même technologie, ce qui est atteste de sa qualité.
Archivage de documents bureautiques classiques
La meilleure façon de s’assurer que les fichiers PDF/A sont bons est de commencer par bien les créer. Pour ce faire, callas pdfaPilot peut convertir les fichiers Microsoft Word, Excel, PowerPoint, Project, Publisher et Visio automatiquement pour vous en fichiers PDF de qualité. Faites-les simplement glisser sur la fenêtre de documents de callas pdfaPilot Desktop ; la conversion s’effectue alors de la meilleure manière possible.
Les documents OpenOffice sont également entièrement reconnus, de même, bien évidemment, que les fichiers Pages et Keynote sous Mac OS X. Avec son moteur Adobe intégré, callas pdfaPilot réalise même pour vous des conversions de qualité des fichiers EPS et PostScript, et ce sans qu’il soit nécessaire d’installer Adobe Acrobat Distiller.
Archivage des e-mails
La messagerie électronique est devenue une composante essentielle de la communication dans la plupart des entreprises. Beaucoup de pays ont adopté des législations et des réglementations relatives à l'archivage des e-mails, que ce soit en vue d'une utilisation future en cas de litige potentiel ou dans le cadre de saines pratiques comptables.
Toutefois, comme les e-mails sont généralement pris en charge par des serveurs de messagerie aux capacités de stockage limitées, rien ne garantit que les courriels que vous recevez aujourd'hui s'y trouveront toujours dans dix ans. En outre, lorsque vous téléchargez un e-mail de votre serveur, il se peut qu'il soit converti dans le format propriétaire du client de messagerie, sans garantie non plus que vous disposerez encore de ce programme à l'avenir. De plus, les pièces jointes nécessitent une visionneuse adéquate pour les différents formats de fichier susceptibles de se présenter. Heureusement, callas pdfaPilot vous permet de conserver ces e-mails, annexes comprises, dans un format PDF/A dont vous avez l'assurance qu'il sera toujours disponible et lisible dans de nombreuses années.
Même dans les environnements non soumis à ces obligations légales, il ne manque pas de bonnes raisons d'archiver les e-mails. Dans notre société moderne, les courriers électroniques recèlent une masse incroyable d'intelligence métier. Il deviendra dès lors de plus en plus important de pouvoir conserver cette information de manière structurée et dans un format identique à celui qui sera utilisé pour les autres documents, et ce tout en ayant la capacité d'effectuer des recherches efficaces dans les e-mails et leurs pièces jointes.
Gestion des EPUB et PDF/UA
Grâce à sa fonctionnalité unique de contrôle de la structure de balisage d'un fichier PDF, callas pdfaPilot assure également l'exportation optimisée vers PDF/UA, le standard en matière d'accessibilité. De plus en plus de législations imposent que les documents soient accessibles universellement pour tout un chacun, y compris les personnes moins valides. En conséquence, le contrôle de conformité au standard PDF/UA a pris de l'importance auprès des prestataires, administrations et entreprises clientes.
PdfaPilot permet toutefois aussi de tirer avantage du balisage PDF dans un domaine très différent: la structure de balises peut ainsi être mise à profit pour la génération automatique de fichiers EPUB à partir de PDF. Cette fonction PDF-EPUB convertit les PDF en livres électroniques, immédiatement consultables sur des appareils mobiles, tels que les smartphones ou les tablettes.
Brochures de PDF Association
Si vous voulez télécharger les brochures de PDF Association, s'il vous plaît, cliquez ici:

Configuration requise
- Mac (Intel): macOS, version 10.7 or newer, 64-bit-compliant
- Windows:
- Windows 7 or newer
- Windows Server 2008 R2 or newer
- Contrôle de conformité des PDF aux standards PDF/A-1, PDF/A-2 et PDF/A-3 (normes ISO 19005-1, 19005-2 et 19005-3)
- Conversion des fichiers PDF en PDF/A-1, PDF/A-2 ou PDF/A-3 et mise en œuvre de toutes les corrections nécessaires
- Conversion des e-mails en PDF/A
- Conversion des fichiers PDF en EPUB et HTML
- Prise en charge de tous les niveaux de conformité PDF/A (de PDF/A-1b à PDF/A-3u)
- Prise en charge du standard PDF/A-3
- Amélioration des PDF en vue de faciliter la création de fichiers PDF/UA
- Incorporation et/substitution des polices manquantes et gestion des glyphes manquants
- Optimisation de toutes les données de couleur pour mise en conformité au standard PDF/A-1
- Ajustement des champs de commentaires et de formulaires aux paramètres par défaut imposés par le standard PDF/A-1
- Suppression des attributs indésirables, comme les calques, ou du contenu interactif, comme les vidéos
- Mise en conformité de la compression d'image au standard PDF/A-1...
- Création de documents PDF/A optimisés pour le Web, en vue d'en faciliter l'accès et la visualisation
- Alignement des métadonnées des documents sur les prescriptions de PDF/A-1...
- Enregistrement de versions de PDF plus récentes, comme le PDF 1.4 tel que défini par PDF/A-1...
- Mise en œuvre d'ajustements et de corrections sans perte d'information
- Génération de rapports clairs, destinés à documenter toutes les procédures de contrôle et de correction
- Amélioration de l'accessibilité globale de PDF/A
- Disponible en anglais, allemand, français, italien, espagnol et japonais
- Possibilité pour les PDF/A-3 de contenir, non seulement d'autres fichiers PDF/A, mais aussi des formats aléatoires tels que Word ou Excel, ou des structures XML
- Conversion en PDF/A garantie; essai automatique de méthodes de conversion différentes de manière à créer le meilleur fichier PDF/A possible
- Conversion améliorée des champs de formulaires et d'annotations, et des métadonnées de niveau objet, en PDF/A-2, et possibilité de supprimer les signatures incompatibles au moment de la conversion en PDF/A-2.
- Création, contrôle ou traitement de factures électroniques ZUGFeRD
Exploitation optimale des métadonnées
- Navigation confortable dans les métadonnées des documents, ainsi que dans les métadonnées de niveau objet pour les images imbriquées dans le document
- Prise en charge de tous les standards de métadonnées sectoriels, dont Dublin Core, IPTC, PRISM, GWG AdTicket/AdsML, PLUS, EXIF et Camera Raw
- Facilitation de la recherche basée sur les métadonnées dans Yahoo, Wikipedia, Amazon, Google et AskMetaFilter
- Prise en charge des données GPS pour une utilisation avec Google Maps, OpenStreetMap et Google Earth
- Exportation XML de toutes les métadonnées de niveaux document et objet pour le suivi d'exploitation des images et des licences
- Définition de schémas d'extension pour vos champs de métadonnées personnalisés, comme l'exige le standard PDF/A-1..., avec le nouveau Metadata Extension Editor
- Incorporation automatique des schémas de métadonnées spécifiques à l'entreprise pour une préservation fiable de ces métadonnées dans vos fichiers PDF/A
Benefits
Solution unique pour tous les besoins d'archivage
- Prise en charge de toutes les versions et variantes de PDF/A
- Contrôle de conformité et correction des documents PDF visant à les rendre conformes
- Reconnaissance totale des métadonnées en soutien des flux d'archivage
- Fonctionnement au choix, à partir d'Adobe Acrobat ou comme application autonome (sans nécessiter l'installation d'Adobe Acrobat ou d'Adobe Reader)
Plus que les PDF
- Conversion des documents de bureautique (Word, Excel, PowerPoint, Visio, Publisher, Project, Open Office) en bons PDF ou PDF/A
- Conversion de formats images (PNG, JPG, TIFF) en PDF ou PDF/A
- Conversion d'e-mails (éventuellement avec leurs pièces jointes) en PDF ou PDF/A
Travailler plus vite avec les documents PDF
- Identifiez rapidement les problèmes de PDF grâce à des contrôles en amont utilisant des profils personnalisables
- Cernez mieux les problèmes de production avec la visionneuse; évaluez les problèmes de surencrage, de résolution d'image et de séparations d'un seul coup d'œil
- Appliquez des correctifs préconfigurés pour résoudre immédiatement les problèmes
- Créez d'un seul clic des listes de corrections et de contrôles à exécuter
- Effectuez le traitement groupé de dossiers comportant jusqu'à 100 documents PDF
Facilité d'emploi inégalée
- Interface utilisateur intuitive qui propose les fonctionnalités à différents niveaux de complexité selon les besoins de chaque type d'utilisateur
- Fenêtre focalisée sur le contrôle de conformité et la conversion en PDF/A
- Interface utilisateur de type Smartphone (le Switchboard), où les niveaux d'utilisation de base sont regroupés clairement par fonctionnalité
- Espace de travail que vous pouvez personnaliser avec toutes les fonctionnalités les plus fréquemment utilisées
- Multitude de profils de contrôle en amont, de contrôles et de correctifs prédéfinis, avec la possibilité de personnaliser ceux qui existe et d'en créer vous-même de nouveaux
pdfaPilot est la solution de conversion des PDF ou des documents natifs et des e-mails en fichiers PDF ou PDF/A robustes et interrogeables pour l'archivage long terme. Il utilise la même technologie PDF/A inébranlable qu'Adobe Acrobat et est disponible pour une utilisation sur poste de travail, via des dossiers actifs, ou est prêt pour une intégration dans les systèmes existants, avec l'interface en ligne de commande ou le kit de développement.
Un point d’entrée unique pour tous vos besoins d’archives
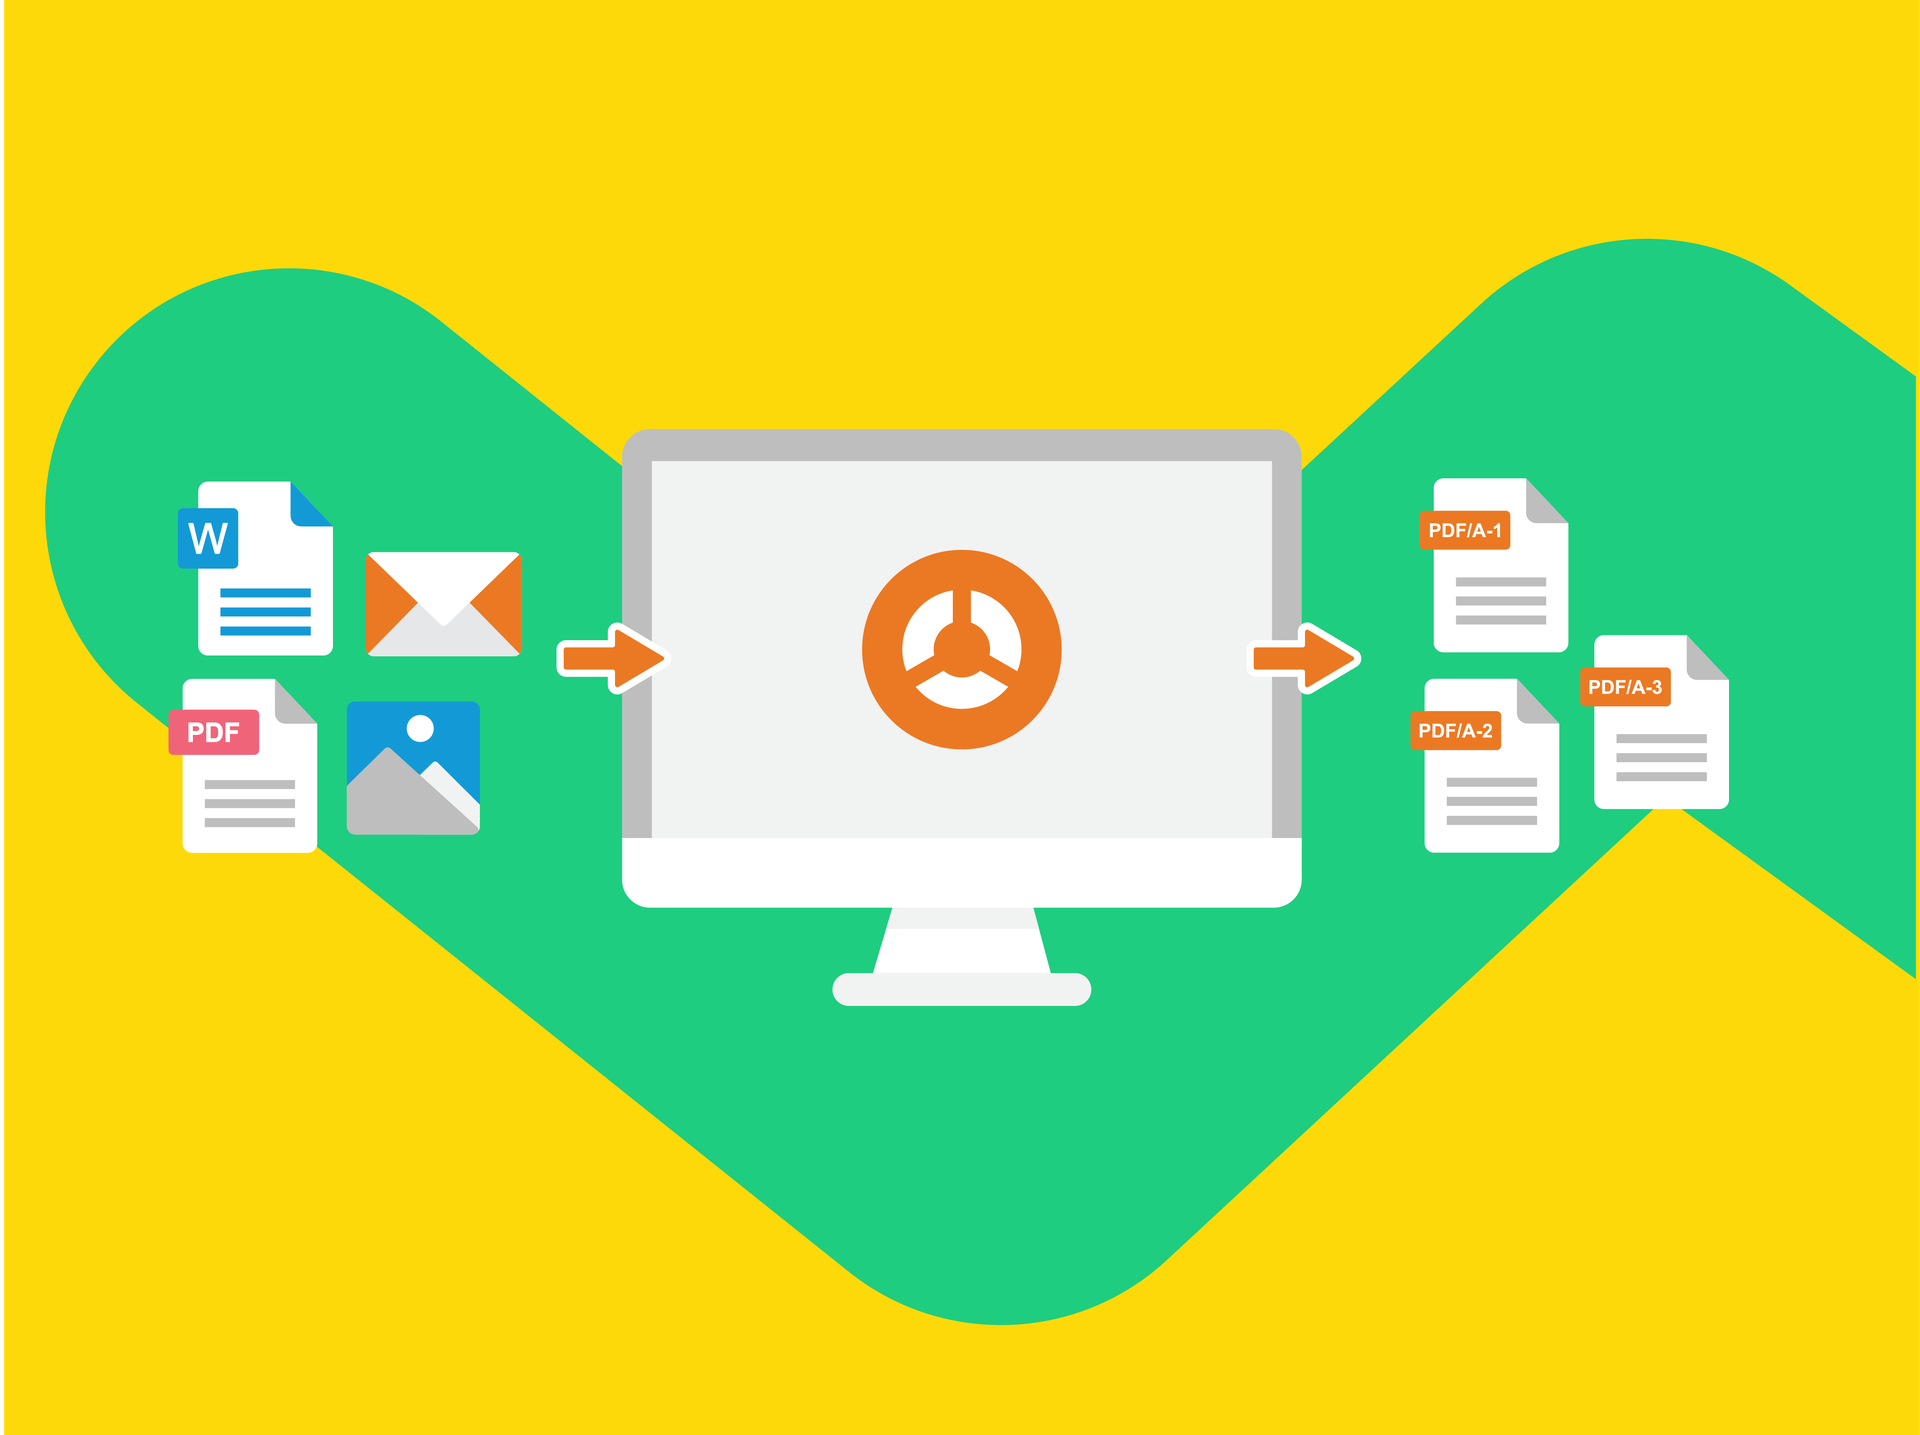
pdfaPilot prend en charge les trois versions de la norme PDF/A : PDF/A-1, PDF/A-2, PDF/A-3. Il propose la conversion de fichiers PDF, mais également de documents bureautiques, d’images et d’e-mails (y compris les pièces jointes) en fichiers PDF/A indexés.
Créez des archives d’e-mails soignées
pdfaPilot convertit vos fichiers d’e-mail en fichiers PDF qui conservent l’apparence des e-mails lorsqu’ils sont consultés ou imprimés par les applications de messagerie correspondantes. Puisque les attentes diffèrent d’une entreprise à l’autre, pdfaPilot utilise une approche basée sur des modèles, qui permet une personnalisation poussée. Les modèles sont particulièrement conviviaux, car basés sur HTML, CSS et JavaScript.
Faites de vos PDF des fichiers universellement accessibles
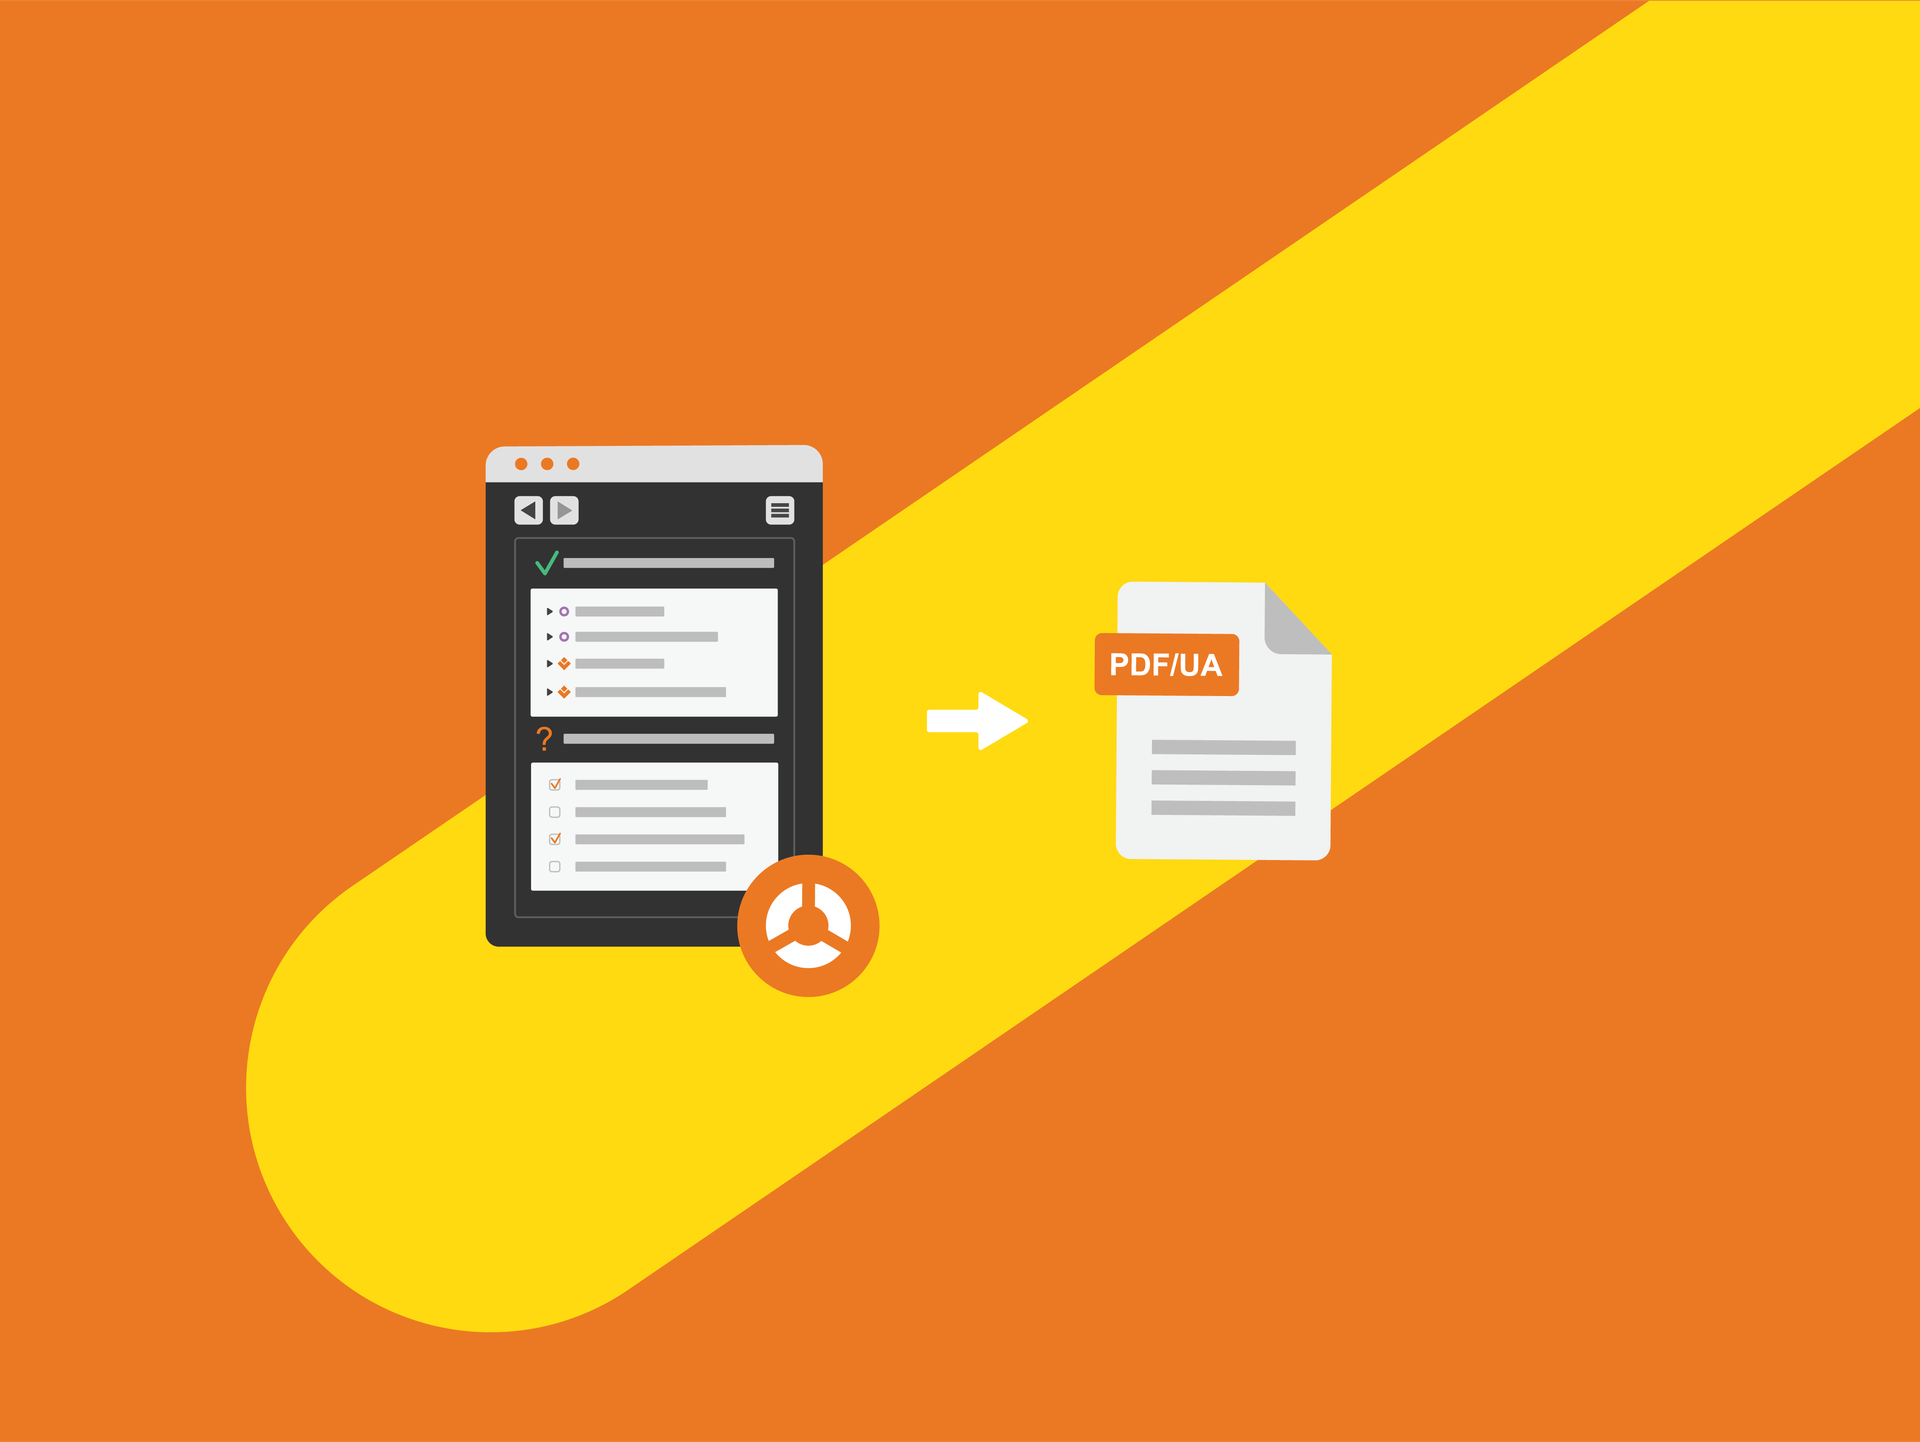
La norme PDF/UA pose un défi unique : certains critères peuvent être vérifiés par un logiciel, mais les autres exigent une intervention humaine. pdfaPilot, pour sa part, prend en charge l’intégralité du processus de vérification. Pour pouvoir procéder à la vérification humaine, des fonctionnalités intégrées permettent de visualiser le document dans une vue Web claire et structurée. Une fois la vérification effectuée, un rapport de conformité complet peut être créé.
Talk to our sales team about this product.
Parlez-nousContact us to get started.
Parlez-nousVersion history
Showing the 5 most recent of 36 releases.
13.1.385
- A free of charge update of pdfaPilot 13 Desktop for owners of a pdfaPilot 13 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Features
- Desktop
- Test mode: Several smaller improvements, e.g. loupe now shows page geometry boxes and page content is displayed in bleed preview
- Process plans
- Compare: A compare report can now also be created if no differences were found
- Action "Split or reorder" now supports output options like folder, prefix and suffix
- New Fixups
- Place file on page
- New Properties
- Size of image
- Size of page object
- Color distance between barcode / matrix code and background
- Bounding box of effectively used page area
- New or enhanced predefined Profiles and Process plans
- Library: PDF Standards:
- Verify compliance with PDF/A-2u: Adjusted algoritm for allowed ToUnicode values
- PDF/UA-1 validation: Element does not use standard tag: Improved detection of recursive RoleMaps
- Library: Prepress, Color and Transparency:
- Added 34 new Profiles for validation and conversion accordingly to the Ghent Workgroup "GWG 2022 R1 Specification"
- Digital Print
- Large Format Printing (LFP)
- Newspaper and Magazine Ads
- Packaging Flexo / Gravure / Offset
- SheetCMYK / SheetSpot
- WebCMYK / WebSpot
- Added 34 new Profiles for validation and conversion accordingly to the Ghent Workgroup "GWG 2022 R1 Specification"
- Library: PDF Standards:
- Actions
- To PDF: Automatic fallback for office files to use OpenOffice/LibreOffice if no MS Office is available (Windows only)
- CLI
- SaveAsImage New optional parameter to define working color spaces for RGB, CMYK and Gray on CLI
- General
- RegEx used in Checks and Fixups: Wrong RegEx syntax will be reported during execution
- Most recent version of Adobe PDF Library integrated (v18.0.4PlusP2z)
- Internal HTML converter updated to callas pdfChip (v2.5.084.1)
Fixes
- Desktop
- Manage Libraries: Problem solved, where importing of a JavaScript based runlist was not properly done
- Process plan editor: Problem solved, where un-protecting a protected Process plan wasn't possible anymore
- Object inspector: Problem solved, where certain PDF files could not be analyzed
- Output preview: Issue fixed, where selected RGB or Gray ICC profiles had no effect on displayed color swatches
- Output preview: Problem solved, where a PDF/X-5n could not be rendered properly
- Switchboard: Issue in batch processing fixed, where certain functions were not properly executed when files were processed on a network path (Windows only)
- Visualizer: Issue fixed, where view was not refreshed when page or document was changed
- Fixups
- Crop to visible based on rendered page: Issue fixed, where CropBox was set larger than MediaBox and an unnecessary ArtBox was introduced
- Crop to visible based on rendered page: Problem solved, where the option "ignore objects using Registration color" was not properly regarded in some cases
- Create link for page objects: Issue fixed, where new link annotations were not positioned on top of existing link annotations
- Create invisible text via OCR: Problem solved, where an improperly nested CropBox/MediaBox had an incomplete result
- Discard hidden layers: Problem solved, where removing a layer could result in missing resources
- Downsample/recompress images:
- Issue fixed, where a FixFailure was reported for ZIP compressed images and re-compression
- Issue fixed, where an JPEG2000 image with smask could not be converted
- Issue fixed, where a smask was not properly handled
- Problem solved, where re-compression was not properly executed on a certain, very large PDF
- Issue fixed, where processing took very long on a certain file with a very high number of very small images (Windows only)
- Remove empty layers: Problem solved, where certain layer-related entries remained in PDF
- Flatten transparency: Issue fixed, where the time out setting was not regarded with certain PDFs
- Subset fonts: Issue fixed, where .notdef glyph used for space characters became visible in certain viewers if its Unicode referenced non-breaking space character
- Place content on page: Issue fixed, where layers were not merged although name, default visibility and Process Steps metadata were matching
- Place content on page: Issue fixed, where the "Order" array of already existing Layers was not properly maintained
- Font processing: Problem solved, where certain result fonts triggered a warning for an unavailable font in certain PDF viewers
- Recompress JPEG2000 images as JPEG: Issue fixed, where certain JPEG2000 image could not be converted
- Remove printer marks: Problem solved, where objects were not removed on all pages if referenced by more than one Form XObject
- Properties
- Number of hits in this check / Number of hits in this check in document: Improved handling of defined limits to avoid unnecessary high memory usage and to improve performance
- Find barcodes: Limit rendering to CropBox even if a custom area is defined and exceeds it to avoid unnecessary memory consumption
- Number of plates: Issue fixed, where smooth shades using only black were reported as "more than 1 plate used"
- Text on page: Problem solved were multiple word repetitions occurred in the trigger value for OCR text
- Has transfer function: Issue fixed, where a TR2 entry was also taken into account in some cases, although not relevant
- Syntax issues: Multiple defined "object streams" with identical order numbers in PDF stream added to internal list of checks
- Actions
- Collection: Problem solved, where the overview page remained emty and no files were embedded in certain cases [FP77375]
- Compare: A wrong path was written for a preview image in cals_params.js when used with a report template
- Duplicate pages: Issue fixed, where the transparency blend color space was not properly maintained
- Save as image:
- Problem solved, where rendering of a certain font was not possible
- Issue fixed, where conversion to TIFF using CMYK and multichannel resulted in an unexpected CMYK color shift
- Issue fixed where rendering outside of the CropBox was no longer possible
- List Variables: Issue fixed, where certain Variable information was missing for a Process plan
- QuickFix: ResavePDF: Problem solved, where wrong header was written in a certain cases
- QuickFix: Enlarge pages: Issue fixed, were certain pattern used in a smooth shade was not properly handled
- Imposition: Issue fixed where a page scaling factor was not properly regarded if JavaScript-based imposition was applied
- To PDF for images:
- Problem solved, where PDF creation resulted in wrong dimension for certain JPEG
- Problem solved, where a certain way of placing text in a SVG resulted in an unexpected result
- Issue fixed, where a CMYK TIFF was not completely converted to PDF
- Problem solved, where transparent regions from CMYK TIFF files became white
- Problem solved, where 8bit CMYK TIFF files with Photoshop alpha layers were not converted to PDF correctly
- Issue fixed, where conversion from TIFF with a smaller BBox than Path-to-clip resulted in a thin white line
- Issue fixed, where conversion of certain high-resolution TIFF resulted in a slightly shifted result
- Issue fixed, where a multichannel TIFF could not be properly converted to PDF
- Problem solved, where a TIFF using the deprecated "Old-style JPEG (in TIFF)" compression could not be converted
- Issue fixed, where an uncompressed grayscale TIFF using 8-Bit could not be converted properly
- Issue fixed, where conversion of a certain TIFF using 16-Bit resulted in gray tiles
- Issue fixed, where a CMYK TIFF using 8-Bit with JPEG compression was converted correctly
- Problem solved, where a TIFF containing an ICC profile with issues could not be converted
- Issue fixed, where a TIFF with Photoshop alpha layers exceeding the dimension of the image itself was not handled properly
- Problem solved, where the dimension of a certain JPG image using a resolution with decimal values was not properly maintained
- To PDF: Problem solved, where a certain type of scaling in a CF2 file was not properly interpreted
- ZUGFeRD: Issue solved, where XMP entry for Version was set to "1p0" instead of "1.0"
- Reports
- XML/JSON: Explicit reporting of default color spaces
- JSON v2: Issue fixed, where no report was generated for password protected PDFs
- JSON v2: Issue fixed, where no report was generated for PDFs with an invalid colorspace type for an image mask
- JSON v2: Issue fixed, where embedded files with AF entry were not listed
- XML: XML schema (XSD) adjusted to cover output_intents entries
- Server
- Issue fixed, where a specified limitation of parallel processes was internally always set to 8 processes even the License Server was used
- CLI
- To PDF: Problem solved, where PostScript-to-PDF conversion could result in unnecessary high memory consumption
- Profile execution: Optimized handling for hits per document if no report option is selected in order to increase performance
- Distributed processing
- Problem solved, where result files of Actions using sub-folders were not transferred back to the Client
- Problem solved, where placing PDFs using the "Place content on page" Fixup was not properly done
- General
- Actions in ProcessPlan: Issue fixed, where a defined sub-folder structure was not regarded
- Process plans: A "File pick up" step now restores the original file name as well
- Process plans: Problem solved, where a combination of "Rename PDF" and "Do not save modified input file" resulted in an error
- Issue fixed, where a Process plan execution was not successful with the first runs but was successful later
- Problem solved, where Profile execution was not successful if certain Fixups were using certain settings
13.2.388
- A free of charge update of pdfaPilot 13 Desktop for owners of a pdfaPilot 13 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Features
- New Properties
- Glyph without contour used for non white space character
- Enhanced Properties
- All barcode-related Checks: Revised and optimized analysis for improved recognition and higher speed
- Report PDF syntax issues: Reporting for invalid end-of-data (EOD) marker in inline images
- Desktop
- Password visibility can be toggled
- Process plans: Multiple steps can now be marked as a group and activated or deactivated together and assigned a variable
- Actions
- Visualizer: Support for RGBA (RGB with transparency) and GrayA (Gray with transparency) as output colorspace for PNG
- Save as image: Support for CMYK + Alpha (CMYK with transparency) for TIFF
- Visualizer: Support for RGBA (RGB with transparency) and GrayA (Gray with transparency) as output colorspace for PNG
- Most recent version of Adobe PDF Library integrated (v18.0.5PlusP1c)
Fixes
- Desktop
- Acrobat Plug-in: Problem solved, where other 3rd-party Plug-ins could not be closed anymore when a PDF was processed by pdfToolbox
- Batch processing: Processing result in crashing application if "Do not save modified input file" was enabled
- Explore PDF: Problem solved, where analysis was not successful if certain data after EOF marker existed
- Explore PDF: Problem solved, where certain PDF with content stream issues was not analyzed properly
- Layer explorer: Issue fixed, where the visibility of cascading layer groups could not be switched on or off properly
- PDF Standards
- Convert to PDF/A-...: Problem solved, where in rare cases a date mismatch between Document Info and XMP Metadata was not adjusted
- Fixups
- Convert TrueType fonts to CFF (for font not matching PDF/A-2 requirements): Issue fixed, where the result PDF had certain font issues
- Create
invisible text via OCR: Issue fixed, where invisible text was not
positioned properly if MediaBox is larger than CropBox
- Create invisible text via OCR: Issue fixed, where an empty text block was generated although the PDF had no text
- Downsample/recompress
images: Issue fixed, where a destination resolution of "0" was not
handled properly and resulted in a missing image
- General font processing: Issue fixed, where certain, rare supplement encoding entries in CFF fonts were not regarded properly, resulting in a changed visual appearance of a glyph
- Place circle|rectangle: Issue fixed, where created layers did not contain certain entries in the layer order array and therefore were not listed as layers in certain PDF viewers
- Remove
annotations: Problem solved, where processing resulted in an error due
to certain, incomplete annotation entries
- Remove pages: Issue fixed, where page labels were not properly restored when pages were deleted
- Scale
pages: Problem solved, where "Fit from outside (cut page)" didn't
reduce the size of TrimBox and BleedBox when needed
- Set layer default to ON/OFF: Problem solved where processing was not executed properly
- Subset fonts: Issue fixed, where processing could change the visual appearance of a particular glyph in a certain case
- All rendering-based Fixups: Improved error message when required memory size could not be allocated
- Checks
- Character code can not be mapped to Unicode: Issue fixed, where certain CMap entries were not properly taken into account
- Find barcodes:
- Issue fixed, where barcode recognition took quite long on certain large pages
- Problem solved, where an unnecessary high amount of memory was used (Linux only)
- Improved recognition of certain, low quality scanned barcodes
- Issue fixed, where an inverted barcode could not be found in certain cases
- Annotation inside BleedBox/TrimBox Problem solved, where annotations were not detected correctly in some cases
- Actions
- E-mail to PDF: Issue solved, where certain tables were not properly formatted [CA1033322]
- ToPDF:
- Problem solved, where the resolution of JPEG images was not maintained in certain cases
- Issue fixed, where MS Publisher files were not converted by MS Office but via LibreOffice
- Issue fixed, where a TIFF using "Old-style JPEG (in TIFF)" compression could not be converted
- E-invoice (ZUGFeRD): Problem solved, where XML schema for validation could not be found if the executable was called from a network path
- Reports
- XML: Issue fixed, where the report contained for a PDF with an embedded file was incomplete
- XML: Schema (XSD) adapted, as certain entries were not clearly defined
- Server
- Job view: Problem solved, where starting or stopping a job did not maintain the scrolling position
- Job view: Problem solved, where starting or stopping a job did not maintain the scrolling position
- CLI
- Several Fixups will now report a more detailed error message if an invalid RegEx is used
- Problem solved, where processing failed due to missing dependencies in certain RHEL (and SLES) based Linux distributions [e.g. an AlmaLinux docker environment]
- General
- Native ARM support for installer on macOS
- RegEx used in Checks and Fixups: Problem solved, where certain incorrect RegEx syntax was not reported properly during execution
- Adjusted version info in "info.plist" to match specified scheme by Apple (macOS only)
- Rendering: Problem solved, where certain colored PDFs were displayed as gray, caused by a specific RGB-ICC profile as transparency blend color space
- Rendering: Issue fixed, where certain, slightly corrupt PDF could no longer be rendered
- "ZuGFeRD" renamed to "e-invoice"
13.2.388.1
- A free of charge update of pdfaPilot 13 Desktop for owners of a pdfaPilot 13 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Fixes
- Process plans:
- Data loss problem fixed that could occur when Process Plans with File Pickup in combination with “Do not save modified input file” were used
14.0.392
- An upgrade to pdfaPilot Server 14, pdfaPilot CLI 14 or pdfaPilot SDK 16 from earlier versions of these products requires a Software Maintenance Agreement (SMA). Please contact your reseller for further information.
Features
Desktop
- Space usage dialogue
- Edit Checks: New "Mouse selector" to define a custom area
- Edit Fixups: New "Mouse selector" to define a custom area
- Library Manager: Support for exporting multiple libraries simultaneously
- Layer explorer: Usability improvements, e.g. "Add missing layer"
- Variables editor: Insert JavaScript allows for importing JavaScript versions of Checks or Fixups
- Variables editor: Predefined sample Runlist imposition objects added
- Profile summary: Overview can be exported as CSV
Process plans
- Editor: Process plans can have annotations
- "Process plan" step: Option to process only certain pages
- "Process plan" step: Process pages individually in a loop
- Create PDF file copy: Option "Copy into variable" to save the path of the created PDF for later use
- Action "Image export": Support for Lab color space for TIFF images
- Action "Split and reorder": Option "Digits for page number"
- Action "Image export": Option "Digits for page number"
- "Add files" step: Option to replace current PDF with another file referenced by a path
- Improved highlighting for steps connected by "File pick up" and "Compare" steps
- Action "Imposition": Results are available in "app.doc.result" for subsequent use via JavaScript
New Fixups
- Place file on path
- Derive stroked from filled vector path
- Replace barcode
- Adjust Form XObject BBoxes to CropBox
- Remove data: Removes data such as annotations, metadata or private data
Enhanced Fixups
- Convert colors: Optimized processing of multipage PDFs and multiple referenced objects
- Convert page content into image: Support for Lab color space
- Flatten transparency: Filter to exclude objects from flattening
- Place barcode: New option to define the background color of a placed barcode
- Place barcode: New section for advanced settings to define additional barcode generation parameters (JSON)
- Place barcode|text|content: Improved reporting when processing results in an error, e.g. due to invalid barcode values or JavaScript issues
- Arbitrary JavaScript-controlled Fixups: Automatic fallback to default values if parameters are missing
New Properties
- Size of document XMP
- Size of object XMP (on page level)
- TrimBox is landscape
- TrimBox is portrait
Enhanced Properties
- Find barcodes: Support for DataBar (RSS 14) codes
- Find barcodes: "Color distance between barcode / matrix code and background” check works better for non-uniform colors
- Operators for text input fields: "is contained in list (ignore upper/lower case)" and "is not contained in list (ignore upper/lower case)"
- Text on page: RegEx capture groups are now reported in trigger values in XML, JSON and JSONv2 reports as well as in JS Variable "app.doc.result" objects
- Various properties: Added Variable support for units
New or enhanced predefined Profiles and Process plans
- Library: Prepress, Color and Transparency:
- Identify color pages: Returns a hit for every page that contains color and stores the result in variables
- Generate 5mm bleed (autoselect bleed generation method)
- All "GWG 2022 R1"-based Profiles: Improved ink coverage checks and of identifying empty pages
- All "GWG 2015" & "GWG 2022" Profiles removed as they have been deprecated by GWG
New or enhanced predefined Fixups
- Library: Prepress, Color and Transparency:
- Generate 5mm bleed (autoselect bleed generation method)
- Derive spot color for haptic print
- Redraw cut line
New Library: Processing Steps
- Profiles and Process plans:
- Prepare PDF using technical colors with Processing Steps layers
- Add Processing Steps layers
- Verify compliance with Processing Steps (ISO 19593-1) for packaging and label (formerly part of the "PDF Standards" Library)
- List Processing Steps metadata information (formerly part of the "PDF Standards" Library)
- Fixups
- Flatten transparency, keep Processing Steps layers
- Checks
- Is Processing Steps layer
New or enhanced Actions
- Create file
- Imposition: The "place content" functionality is now available in JavaScript-based impose scripts.
- ToPDF: Support for HEIF and HEIC images
- SaveAsImage: Support for Lab color space for TIFF images
New or enhanced Quick Fix
- Apply 2D transformation matrix to page content: Allows scaling, rotation, translation and skewing of content
Most recent version of Adobe PDF Library integrated (v18.0.5PlusP1g)
- Most recent version of Adobe PDF Converter integrated (PostScript to PDF conversion; v3.2.0Plus1m)
- Internal HTML converter updated to callas pdfChip (v2.6.096)
Fixes
Desktop
- Workspace: Problem solved, where Process plan setting "Do not save modified input file" was not respected
Process plans
- Reports: Issue fixed, where a Variable defined for the PDF overview report template was not respected
- Do not save modified input file: Problem solved, where files were not handled properly if loops existed in the Process plan
Fixups
- Convert colors: Problem solved, where processing time increased due to non-optimal handling of shared resources
- Convert page content into image: Improved handling of existing Output Intents for rendering if object filters are used
- Convert page content into image: Improved handling of existing Output Intent when objects were excluded from bleed creation to ensure correct color values
- Crop pages: Problem solved, where certain, unnecessary content stream operators were not handled properly and resulted in shifted content
- Make document XMP Metadata compliant: Problem solved, where processing resulted in a failure
- Optimize the PDF for fast web view: Issue fixed, where execution was not reported
- Place content on page: JavaScript errors are now reported if a failure occurs due to this error
- Place file on page: New options to specify width and height for placed file
- Remove invisible image data: Problem solved, where image visually disappeared due to a specific SoftMask usage
- Remove objects: Problem solved, where Form XObjects used for bleed remained outside page area
- Set layer initial print state: Problem fixed, where initial state could not be set to "Never prints" in certain case
- Place ... based Fixups: Issue fixed, where only one Fixup was reported, when several Fixups were executed
- Subset fonts: Problem solved, where certain supplement encodings were not handled correctly, resulting in incomplete rendering with certain viewers [FP80291]
- General font processing: Problem solved, where a double SPACE was inserted, although not necessary
- General font processing: Problem solved, where unnecessary entries in the encoding of a CFF font caused problems on certain output devices
Checks
- Is landscape: Changed behavior, now uses the CropBox to determine orientation (was BleedBox before)
- Is portrait: Changed behavior, now uses the CropBox to determine orientation (was BleedBox before)
- Image is not valid: Problem solved, where analysis could not be executed properly
- Find barcodes: Problem solved, where size of found "RSS Extended Stacked" barcodes was not determined correctly
- Find barcodes: Issue fixed, where a barcode was reported for a layer, although not assigned to this layer
- Sifter-based properties: Issue fixed, where certain clipped smooth shades were incorrectly interpreted
- General font analysis: Problem solved, where a certain unusually high value in Font CMaps resulted in unnecessary long processing and memory consumption
Process plans
- Action "Split and reorder": Issue fixed, where output filename was indexed instead of being derived from the page number
Actions
- ToPDF:
- Images: Issue fixed, where certain Tiff files could not be converted to PDF
- PostScript:
- Problem solved, where clippings were not handled correctly in some cases
- Problem solved, where content was not handled properly when certain PostScript constructions were used
- Issue fixed, where not all page geometry boxes were retained after conversion
- Extract images: Problem solved, where certain images were inverted when exported
- Extract content: Problem fixed where certain combined UTF-16 code (to represent a UTF-32 character) was not handled correctly (Linux only)
- SaveAsImage: Problem solved, where rendering could not be performed correctly for certain file dimensions at certain resolutions
- SaveAsImage: Issue fixed, where exported multichannel TIFF files were inverted when created with high resolution
Reports
- XML: Problem solved, where report creation failed in a certain case
- XML: Schema (XSD) adapted, as certain entries were not clearly defined
General
- Problem solved, were certain corrupt metadata could result in an unstable behavior
- JavaScript Variables: Problem solved, where accessing invalid data could result in unstable behavior in certain cases
System requirements
- Mac: macOS version 10.15 or newer, 64-bit-compliant
14.1.395
- A free of charge update of pdfaPilot 14 Desktop for owners of a pdfaPilot 14 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Features
Desktop
- Testmode: A new "Cancel" button next to the progress bar, makes it easier to cancel the run when it takes too long, while keeping the Check results collected so far
- ProcessPlan editor: Improved "snap to grid" functionality for steps and annotations
- *ProcessPlan editor: Annotations now support different text alignment options
Fixups
- Remove invisible image data: New option "Duplicate multiple used images if necessary"
Actions
- MergePDF: Pagelabels of input files will now be maintained
- Internal HTML converter updated to callas pdfChip (v2.6.098)
Fixes
Desktop
- Object Inspector: Problem solved, where the position of an object was not properly transferred to the derived Check
- Search Libraries dialog: Fixed an issue, where entries in the Libraries popup were not sorted alphabetically
New Fixups
- Remove broken link annotations and bookmarks
New Properties
- Link annotation uses broken destination
- Bookmark uses broken destination
Enhanced Profiles
- Library: PDF Standards:
- Convert to PDF/X-1...: "Recompress JPEG2000 images as JPEG" has been added as an additional default Fixup
Fixups
- Add missing layer / Put objects on layer: Issue fixed, where created layer structure contained an empty group entry
- Convert TrueType to CFF: Problem solved, where glyphs were not properly handled due to some rare encoding entries
- Create invisible text via OCR: Issue fixed, where text was created with an offset if the boxes were not properly nested
- Downsample/compress bitmap images: Problem solved, where certain CCITT-decoded inline images were not converted properly
- Place rectangle: Problem solved, where the position differed if the rounded corner value was set
- Remove from layer: Problem solved, where certain layer structures where not properly maintained and objects could become invisible
- Remove XMP metadata: Problem solved, where not all defined metadata was removed when multiple Fixup settings were defined
- Remove XMP metadata: Issue fixed, where processing resulted in an error when "Set Title entry to filename" was executed in the same Profile
- Subset fonts: Problem solved, where certain CID encoding for space characters could result in glyphs vanishing
- General font processing: Problem solved, where certain, corrupt cmap structures were not properly detected or repaired
Checks
- Find barcodes:
- Issue fixed, where the number of barcodes found varied from run to run in certain cases (Windows only)
- Improved recognition of QR code quiet zones when the surrounding background is just slightly different to the background of the barcode area
- Improved barcode detection and more accurate dimension calculation
- Font is not valid: Improved recognition of certain font issues where glyphs were not listed correctly in the necessary tables
Actions
- Extract XMP metadata: Issue fixed, where images in Form XObjects with no dimensions were not handled properly
- Modify Structures: Problem solved, where bookmarks using the "Open" state were not inserted correctly
- To PDF: Problem solved, where certain 16-bit TIFF images could not be converted to PDF properly
- To PDF: Problem solved where temporary, internal files being created during conversion to PDF were not being deleted even though the final PDF was saved
CLI
- Problem solved, where placing content failed due to a missing "libatomic1" package in certain, Linux distributions
- Merge PDF: Issue fixed, where attempting to merge a corrupt file resulted in an incomplete merge instead of triggering an error
General
- Profile processing: Discontinued creation of dedicated log files in the TEMP folder of the application if processing errors occur
- Improved recognition and repair of certain invalid SMask definitions
- Problem solved, where internal content stream optimization did not set the color space for used SoftMasks not correctly in some cases, which could result in display issues
- Process plans: Problem solved, where temporary files that were marked for deletion after processing were still listed as created files in the output
- Process plans: Problem solved, where requesting an XML report including ink coverage for a step resulted in an error upon execution
- Problem solved, where the application became unstable when OpenCV system libraries were installed on the same system (macOS only)