pdfaPilot Desktop
pdfaPilot converteert PDF's of native documenten en e-mails in robuuste, doorzoekbare PDF- of PDF/A-bestanden voor langdurige archivering.
In veel omgevingen bepaalt de regelgeving dat alle communicatie over specifieke onderwerpen gedurende een bepaalde periode worden gearchiveerd. pdfaPilot helpt je om te verzekeren dat je documenten worden gearchiveerd en tot ver in de toekomst beschikbaar blijven.
Zorg ervoor dat je documenten en e-mails een leven lang meegaan
In veel omgevingen heersen er regels die vereisen dat alle communicatie over specifieke onderwerpen wordt gearchiveerd en bewaard gedurende een bepaalde periode. De vereiste archiverings- en bewaringstermijn kan sterk verschillen, van een paar jaar tot tientallen jaren.
Het populairste formaat voor archivering is gedefinieerd in de ISO-norm PDF/A (PDF for Archiving). Deze ISO-norm definieert drie verschillende PDF/A-versies. callas pdfaPilot kan al je documenten en e-mails automatisch converteren naar de PDF/A-versie die vereist is voor je doeleinden. Het opnemen van extra informatie (metadata) wordt volledig ondersteund. Bovendien is de oplossing eenvoudig configureerbaar. Zo kan je de oplossing aanpassen aan je workflow, in plaats van dat je je workflow moet aanpassen aan de oplossing.
Het archiveren van documenten is een bedrijfskritisch proces in moderne workflows. Daarom is callas pdfaPilot uitgebreid getest. Tests zoals de Isartor Test Suite tonen aan dat callas pdfaPilot voldoet aan de ISO-normen. Het feit dat callas pdfaPilot exact dezelfde technologie gebruikt als Adobe Acrobat, de de facto standaard, getuigt van de kwaliteit van callas pdfaPilot.
Typische kantoordocumenten archiveren
De beste manier om hoogkwalitatieve PDF/A-bestanden te verkrijgen, bestaat erin ze van de eerste keer op de goede manier te maken. Je kan dat overlaten aan callas pdfaPilot, dat Microsoft Word-, Excel-, PowerPoint-, Project-, Publisher- en Visio-bestanden automatisch kan converteren naar hoogkwalitatieve PDF-bestanden. Sleep ze gewoon naar het documentvenster van callas pdfaPilot Desktop en de conversie wordt dan op de best mogelijke manier uitgevoerd.
Ook OpenOffice-documenten worden volledig ondersteund, evenals Mac OS X Pages- en Keynote-bestanden. Dankzij de geïntegreerde Adobe engine kan je zelfs op pdfaPilot vertrouwen voor een hoogkwalitatieve conversie van EPS- en PostScript-bestanden. En dit zonder dat Acrobat Distiller hoeft te zijn geïnstalleerd.
E-mail archiveren
Vandaag zijn e-mails in de meeste organisaties een essentieel onderdeel van de zakelijke communicatie. In veel landen heersen er wetten en regels die vereisen dat dergelijke communicatie wordt gearchiveerd voor gebruik in eventuele toekomstige rechtszaken of in het kader van goede boekhoudkundige praktijken.
E-mailverkeer verloopt meestal via e-mailservers met een beperkte opslagcapaciteit. Er is dus geen garantie dat een e-mail die je vandaag ontvangt, tien jaar later nog op de server zal staan. Wanneer je de e-mail downloadt van je server, wordt deze mogelijk geconverteerd naar het eigen formaat van je e-mailtoepassing. Ook hier geldt dat er geen garantie is dat je in de toekomst nog toegang zal hebben tot die toepassing. Daar komt nog bij dat de bijlagen in de mails uiteenlopende bestandsformaten hebben die een geschikte viewer vereisen om ze te kunnen weergeven. Gelukkig stelt callas pdfaPilot je in staat om je e-mails en alle bijlagen te bewaren in een PDF/A-formaat dat vele jaren later nog steeds toegankelijk en leesbaar zal zijn.
Maar zelfs in omgevingen waar er geen dergelijke regels voor archivering en bewaring gelden, zijn er goede redenen om e-mails te archiveren. In onze moderne samenleving bevatten e-mails een verbazingwekkende hoeveelheid zakelijke informatie. Het zal steeds belangrijker worden om enerzijds die informatie te kunnen bewaren op een gestructureerde manier en in een formaat dat wordt gebruikt voor andere documenten, en anderzijds al je documenten en je e-mails en bijhorende bijlagen op efficiënte wijze te kunnen doorzoeken.
Verwerking tot EPUB en PDF/UA
Dankzij zijn unieke controlefunctie voor de codestructuur in een PDF-bestand biedt callas pdfaPilot ook geoptimaliseerde export naar PDF/UA (PDF for Universal Accessibility), de norm voor toegankelijkheid. Steeds meer wetgeving vereist dat documenten toegankelijk zijn voor iedereen, ook voor mensen met een lichamelijke handicap. Daardoor wordt controle op voldoening aan de PDF/UA-norm steeds belangrijker voor service providers, overheden en bedrijven.
Maar met pdfaPilot kan je de voordelen van PDF-codes ook optimaal benutten voor een compleet ander doel:
De codestructuur kan worden gebruikt om automatisch EPUB-bestanden te maken van PDF’s. Deze PDF-naar-EPUB-functie converteert PDF’s naar eBook-bestanden die gebruiksklaar zijn voor weergave op mobiele apparaten zoals smartphones of tablets.
PDF Association brochures
Als je de PDF Association brochures wil downloaden, gelieve dan hier te klikken:

Systeemvereisten
- Mac (Intel): macOS, version 10.7 or newer, 64-bit-compliant
- Windows:
- Windows 7 or newer
- Windows Server 2008 R2 or newer
Belangrijkste kenmerken
- Controleert of PDF’s voldoen aan de norm PDF/A-1, PDF/A-2 en PDF/A-3 (ISO 19005-1, ISO 19005-2 en ISO 19005-3)
- Converteert PDF-bestanden naar PDF/A-1, PDF/A-2 of PDF/A-3 en implementeert alle noodzakelijke correcties
- Converteert e-mails naar PDF/A
- Converteert PDF-bestanden naar EPUB en HTML
- Ondersteunt alle conformiteitsniveaus van PDF/A (van PDF/A-1b tot PDF/A-3u)
- Ondersteunt de PDF/A-3-norm
- Verbetert PDF’s om de aanmaak van PDF/UA-bestanden te vergemakkelijken
- Sluit ontbrekende lettertypes in en/of vervangt ze en lost fouten op die worden veroorzaakt door ontbrekende schrifttekens (glyphs)
- Optimaliseert alle kleurgegevens om ervoor te zorgen dat ze conform de PDF/A-1-norm zijn
- Past opmerkingen en formuliervelden aan de door de PDF/A-1-norm vereiste standaardinstellingen aan
- Verwijdert ongewenste kenmerken zoals lagen of interactieve inhoud zoals films
- Zorgt ervoor dat de afbeeldingscompressie voldoet aan de PDF/A-1...-norm
- Maakt PDF/A-documenten die geoptimaliseerd zijn voor het web met het oog op gemakkelijkere toegang en weergave
- Zorgt ervoor dat metadata conform de PDF/A-1...-vereisten zijn
- Slaat nieuwere PDF-versies op als PDF 1.4, zoals gespecificeerd door PDF/A-1...
- Implementeert aanpassingen en correcties zonder dat er informatie verloren gaat
- Genereert duidelijke rapporten om alle test- en correctieprocedures te documenteren
- Verbetert de toegankelijkheid van PDF/A over de hele lijn
- De gebruikersinterface is beschikbaar in het Engels, Duits, Frans, Italiaans, Spaans en Japans
- PDF/A-3-verzamelingen kunnen ook andere PDF/A-bestanden bevatten, evenals eender welke andere bestandsformaten (bijv. Word- of Excel-bestanden of XML-structuren)
- Gegarandeerde conversie naar PDF/A: probeert automatisch verschillende conversiemethoden om het best mogelijke PDF/A-bestand te maken
- Biedt verbeterde conversie naar PDF/A-2 wat betreft formuliervelden, annotaties en metadata op objectniveau en de mogelijkheid om incompatibele handtekeningen te verwijderen bij de conversie naar PDF/A-2
- Maakt, controleert of verwerkt ZUGFeRD-facturen
Haal het maximum uit metadata
- Maakt het gemakkelijk om te bladeren door de metadata van een document en ook de metadata op objectniveau voor afbeeldingen die ingesloten zijn in het document
- Ondersteunt alle relevante industriestandaarden op het gebied van metadata, zoals Dublin Core, IPTC, PRISM, GWG AdTicket/AdsML, PLUS, EXIF en Camera Raw
- Vergemakkelijkt op metadata gebaseerde zoekopdrachten in Yahoo, Wikipedia, Amazon, Google en Ask MetaFilter
- Ondersteunt GPS-data voor gebruik in combinatie met Google Maps, OpenStreetMap en Google Earth
- Biedt XML-export van alle metadata van het document en metadata op objectniveau om het gebruik van afbeeldingen en licenties te kunnen bijhouden
- Definieert met de nieuwe Metadata Extension Editor uitbreidingsschema’s voor aangepaste metadatavelden zoals vereist door de PDF/A-1...-norm
- Sluit je bedrijfsspecifieke metadataschema’s automatisch in je PDF/A-bestanden in voor betrouwbare conservering van metadata
Benefits
One-stopshop voor alle archiveringsbehoeften
- Ondersteunt alle versies en niveaus van PDF/A
- Controleert of PDF-documenten voldoen aan de norm en corrigeert ze om ze conform te maken als ze niet voldoen
- Biedt volledige ondersteuning voor aangepaste metadata met het oog op workflows voor archivering
- Stelt je in staat om het te gebruiken vanuit Adobe Acrobat of als zelfstandige toepassing (zonder Adobe Acrobat of Adobe Reader te moeten installeren)
Ondersteunt meer dan PDF alleen
- Converteert kantoordocumenten (Word-, Excel-, PowerPoint-, Visio-, Publisher-, Project-, OpenOffice-documenten) naar hoogkwalitatieve PDF- of PDF/A-documenten
- Converteert afbeeldingsformaten (PNG, JPG, TIFF) naar PDF of PDF/A
- Converteert e-mails (optioneel inclusief bijlagen) naar PDF of PDF/A
Versnelt de manier waarop je werkt met PDF-documenten
- Identificeer snel PDF-problemen dankzij preflighting met aanpasbare profielen
- Zoom in op productieproblemen met behulp van de visualizer voor een grondiger analyse; beoordeel problemen met de totale inktdekking, de resolutie van afbeeldingen en kleurscheidingen in één oogopslag
- Pas vooraf geconfigureerde herstellingen toe om problemen direct op te lossen
- Maak lijsten met correcties en controles die je met een simpele klik in één keer kan toepassen
- Verwerk mappen met tot wel 100 PDF-documenten als een batch
Ongeëvenaard gebruiksgemak
- Intuïtieve gebruikersinterface met zowel eenvoudige als geavanceerdere functionaliteit, waardoor zowel onervaren gebruikers als doorgewinterde professionals op hun wenken worden bediend
- Venster om in één stap voor het geopende PDF-bestand te controleren of het voldoet aan de gewenste PDF/A-norm of het ernaar te converteren
- Smartphoneachtige gebruikersinterface (het Switchboard) met laagdrempelige functionaliteit, die overzichtelijk geordend is in groepen
- Een werkruimte die je kan aanpassen voor snelle toegang tot alle functies die je vaak gebruikt
- Massa’s vooraf gedefinieerde preflightprofielen, controles en herstellingen met de mogelijkheid om deze naar wens aan te passen of eigen preflightprofielen te maken
pdfaPilot is dé oplossing voor conversie van PDF- of andere documenten en e-mails naar hoogkwalitatieve, doorzoekbare PDF- of PDF/A-bestanden voor archivering op lange termijn. Het maakt gebruik van dezelfde uiterst betrouwbare PDF/A-technologie als Adobe Acrobat en is beschikbaar voor desktopgebruik, via hot folders of voor integratie in bestaande systemen via een command-line interface of een software development kit.
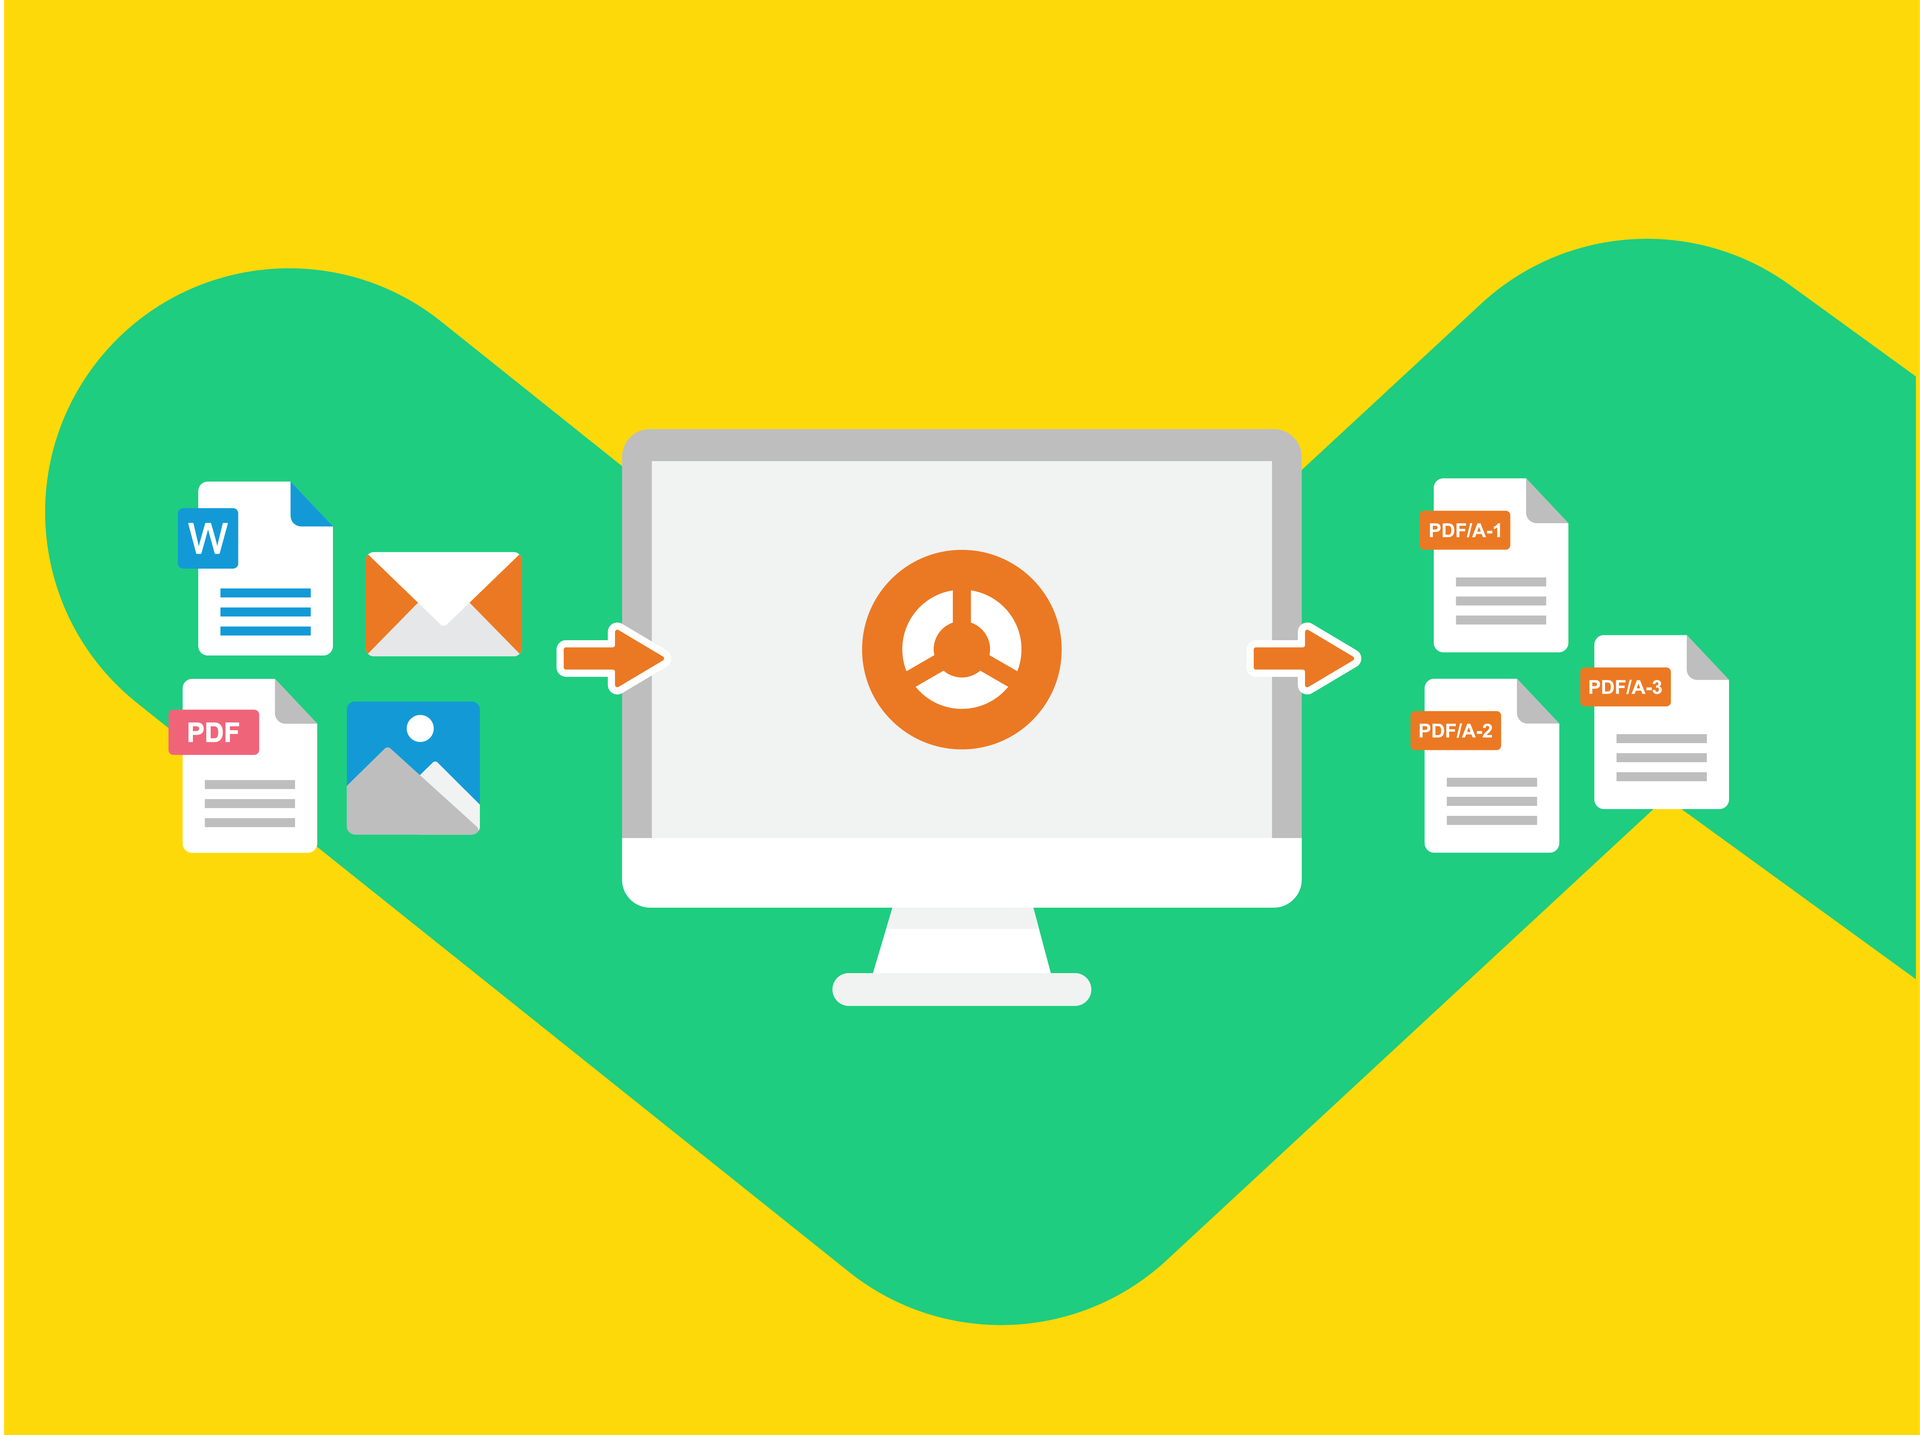
Onestopshop voor al je archiveringsbehoeften
pdfaPilot ondersteunt de drie PDF/A-versies: PDF/A-1, PDF/A-2 en PDF/A-3. De tool converteert niet alleen PDF-bestanden, maar ook Office-documenten, afbeeldingsformaten en e-mails (en hun bijlagen) naar doorzoekbare PDF/A-bestanden.
Buitengewone e-mailarchieven
pdfaPilot converteert e-mailbestanden naar PDF-bestanden die in e-mailtoepassingen als e-mails worden weergegeven of afgedrukt. Omdat niet alle organisaties dezelfde verwachtingen hebben, gebruikt pdfaPilot een templatebenadering die veel aanpassingen op maat mogelijk maakt. De templates zijn gebaseerd op HTML, CSS en JavaScript en dus heel gebruiksvriendelijk.
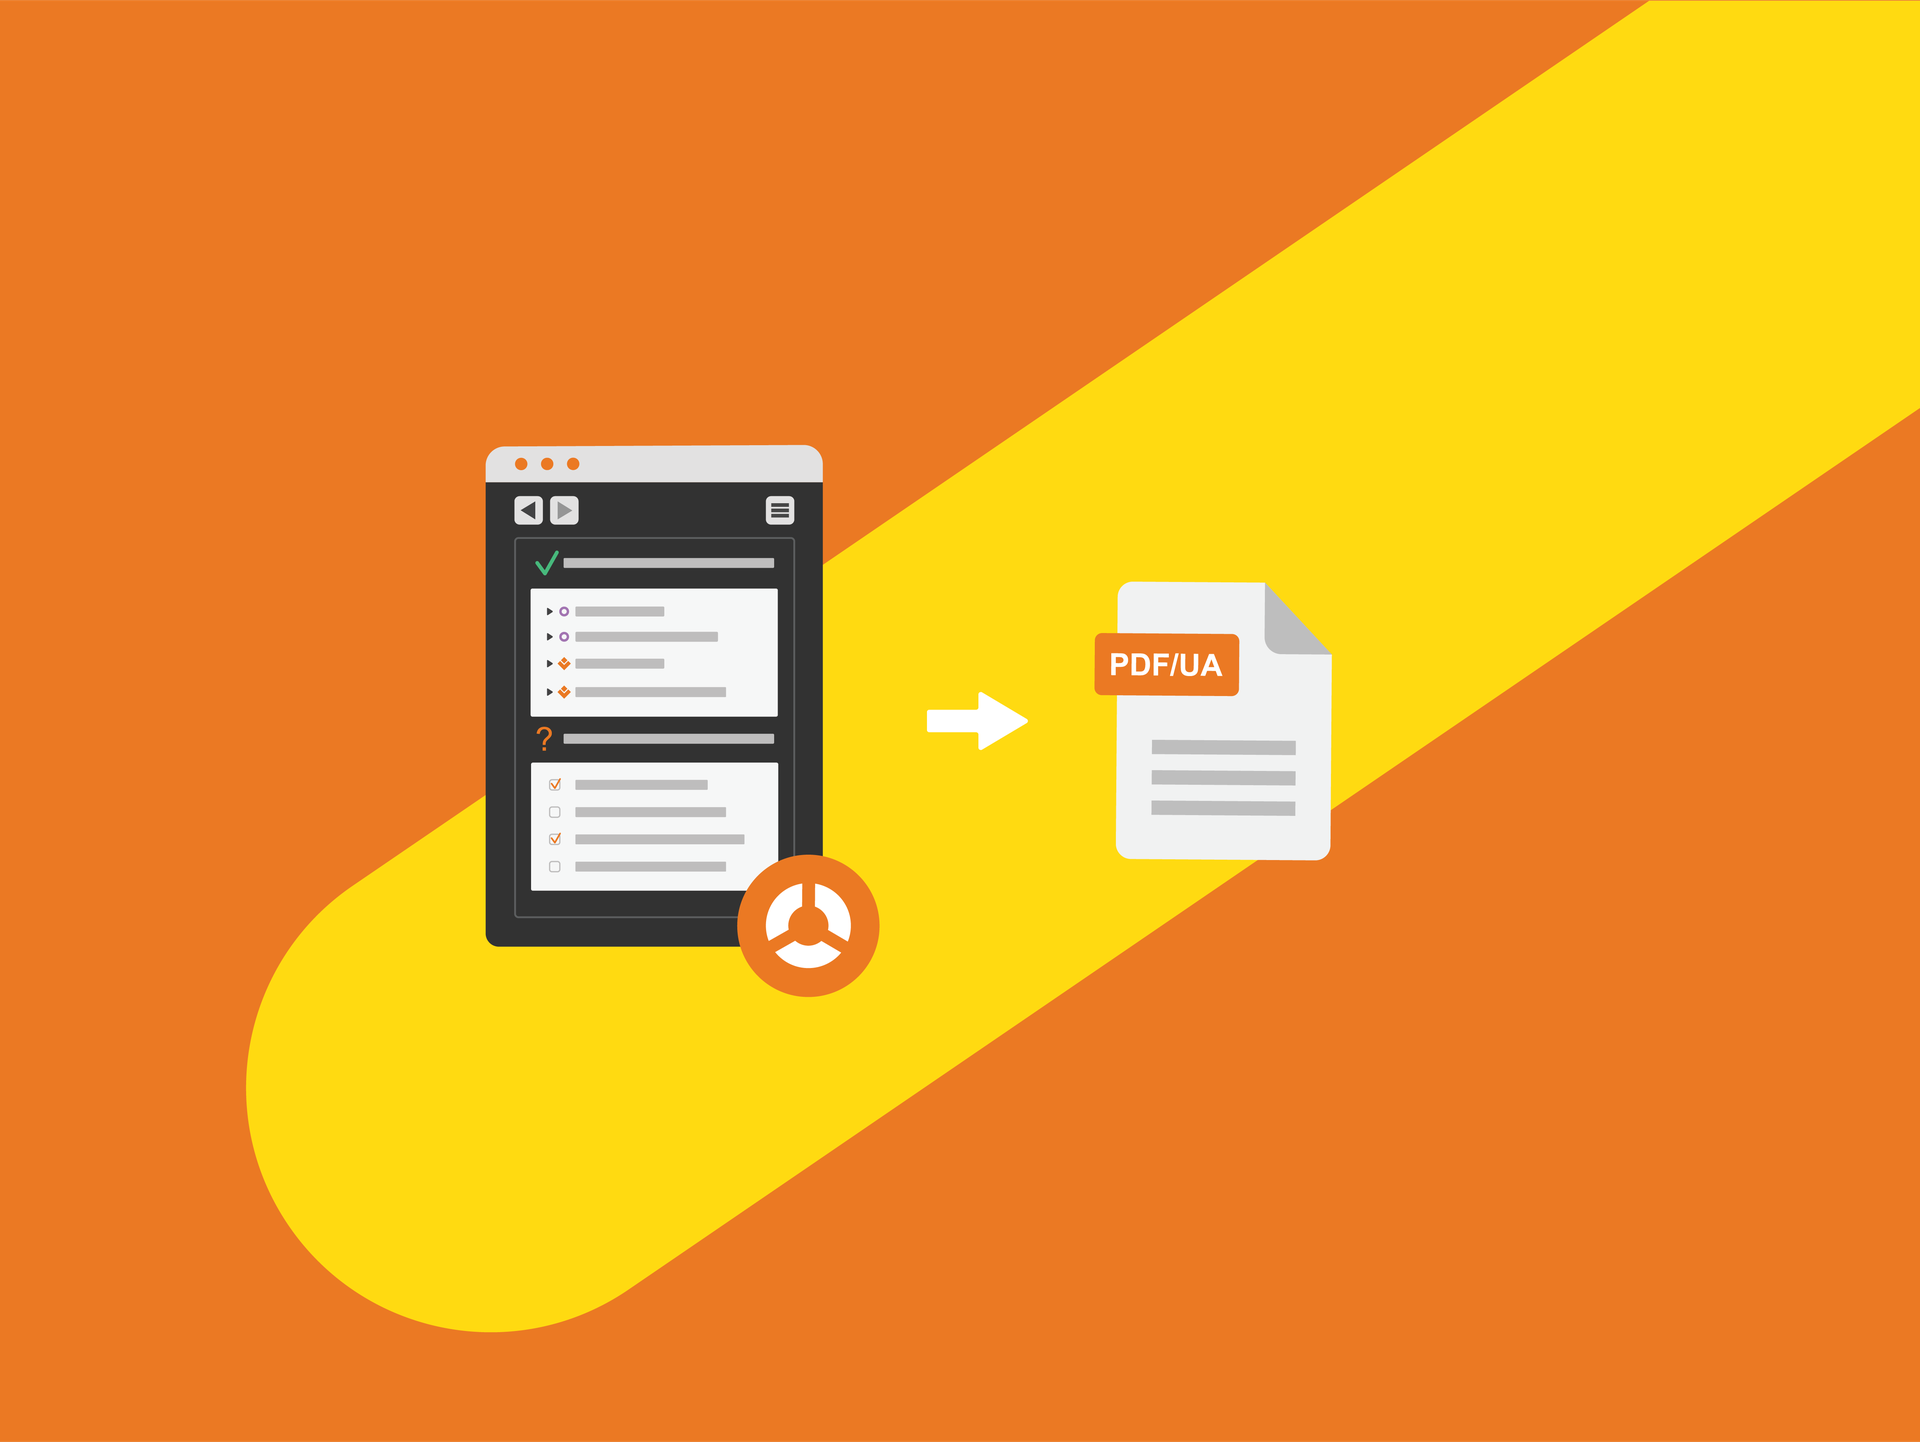
Maak je PDF-document universeel toegankelijk
PDF/UA stelt je voor een unieke uitdaging: een deel van de vereisten kan door software worden geverifieerd, maar het andere deel vereist verificatie door de mens. pdfaPilot neemt het eerste deel van het verificatieproces volledig voor zijn rekening. Voor de verificatie door de mens worden de functies geïntegreerd in een gestructureerde, gemarkeerde weergave op het web. Na de verificatie kan een volledig compliance rapport worden aangemaakt.
Talk to our sales team about this product.
Praat met onsContact us to get started.
Praat met onsVersion history
Showing the 5 most recent of 36 releases.
13.1.385
- A free of charge update of pdfaPilot 13 Desktop for owners of a pdfaPilot 13 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Features
- Desktop
- Test mode: Several smaller improvements, e.g. loupe now shows page geometry boxes and page content is displayed in bleed preview
- Process plans
- Compare: A compare report can now also be created if no differences were found
- Action "Split or reorder" now supports output options like folder, prefix and suffix
- New Fixups
- Place file on page
- New Properties
- Size of image
- Size of page object
- Color distance between barcode / matrix code and background
- Bounding box of effectively used page area
- New or enhanced predefined Profiles and Process plans
- Library: PDF Standards:
- Verify compliance with PDF/A-2u: Adjusted algoritm for allowed ToUnicode values
- PDF/UA-1 validation: Element does not use standard tag: Improved detection of recursive RoleMaps
- Library: Prepress, Color and Transparency:
- Added 34 new Profiles for validation and conversion accordingly to the Ghent Workgroup "GWG 2022 R1 Specification"
- Digital Print
- Large Format Printing (LFP)
- Newspaper and Magazine Ads
- Packaging Flexo / Gravure / Offset
- SheetCMYK / SheetSpot
- WebCMYK / WebSpot
- Added 34 new Profiles for validation and conversion accordingly to the Ghent Workgroup "GWG 2022 R1 Specification"
- Library: PDF Standards:
- Actions
- To PDF: Automatic fallback for office files to use OpenOffice/LibreOffice if no MS Office is available (Windows only)
- CLI
- SaveAsImage New optional parameter to define working color spaces for RGB, CMYK and Gray on CLI
- General
- RegEx used in Checks and Fixups: Wrong RegEx syntax will be reported during execution
- Most recent version of Adobe PDF Library integrated (v18.0.4PlusP2z)
- Internal HTML converter updated to callas pdfChip (v2.5.084.1)
Fixes
- Desktop
- Manage Libraries: Problem solved, where importing of a JavaScript based runlist was not properly done
- Process plan editor: Problem solved, where un-protecting a protected Process plan wasn't possible anymore
- Object inspector: Problem solved, where certain PDF files could not be analyzed
- Output preview: Issue fixed, where selected RGB or Gray ICC profiles had no effect on displayed color swatches
- Output preview: Problem solved, where a PDF/X-5n could not be rendered properly
- Switchboard: Issue in batch processing fixed, where certain functions were not properly executed when files were processed on a network path (Windows only)
- Visualizer: Issue fixed, where view was not refreshed when page or document was changed
- Fixups
- Crop to visible based on rendered page: Issue fixed, where CropBox was set larger than MediaBox and an unnecessary ArtBox was introduced
- Crop to visible based on rendered page: Problem solved, where the option "ignore objects using Registration color" was not properly regarded in some cases
- Create link for page objects: Issue fixed, where new link annotations were not positioned on top of existing link annotations
- Create invisible text via OCR: Problem solved, where an improperly nested CropBox/MediaBox had an incomplete result
- Discard hidden layers: Problem solved, where removing a layer could result in missing resources
- Downsample/recompress images:
- Issue fixed, where a FixFailure was reported for ZIP compressed images and re-compression
- Issue fixed, where an JPEG2000 image with smask could not be converted
- Issue fixed, where a smask was not properly handled
- Problem solved, where re-compression was not properly executed on a certain, very large PDF
- Issue fixed, where processing took very long on a certain file with a very high number of very small images (Windows only)
- Remove empty layers: Problem solved, where certain layer-related entries remained in PDF
- Flatten transparency: Issue fixed, where the time out setting was not regarded with certain PDFs
- Subset fonts: Issue fixed, where .notdef glyph used for space characters became visible in certain viewers if its Unicode referenced non-breaking space character
- Place content on page: Issue fixed, where layers were not merged although name, default visibility and Process Steps metadata were matching
- Place content on page: Issue fixed, where the "Order" array of already existing Layers was not properly maintained
- Font processing: Problem solved, where certain result fonts triggered a warning for an unavailable font in certain PDF viewers
- Recompress JPEG2000 images as JPEG: Issue fixed, where certain JPEG2000 image could not be converted
- Remove printer marks: Problem solved, where objects were not removed on all pages if referenced by more than one Form XObject
- Properties
- Number of hits in this check / Number of hits in this check in document: Improved handling of defined limits to avoid unnecessary high memory usage and to improve performance
- Find barcodes: Limit rendering to CropBox even if a custom area is defined and exceeds it to avoid unnecessary memory consumption
- Number of plates: Issue fixed, where smooth shades using only black were reported as "more than 1 plate used"
- Text on page: Problem solved were multiple word repetitions occurred in the trigger value for OCR text
- Has transfer function: Issue fixed, where a TR2 entry was also taken into account in some cases, although not relevant
- Syntax issues: Multiple defined "object streams" with identical order numbers in PDF stream added to internal list of checks
- Actions
- Collection: Problem solved, where the overview page remained emty and no files were embedded in certain cases [FP77375]
- Compare: A wrong path was written for a preview image in cals_params.js when used with a report template
- Duplicate pages: Issue fixed, where the transparency blend color space was not properly maintained
- Save as image:
- Problem solved, where rendering of a certain font was not possible
- Issue fixed, where conversion to TIFF using CMYK and multichannel resulted in an unexpected CMYK color shift
- Issue fixed where rendering outside of the CropBox was no longer possible
- List Variables: Issue fixed, where certain Variable information was missing for a Process plan
- QuickFix: ResavePDF: Problem solved, where wrong header was written in a certain cases
- QuickFix: Enlarge pages: Issue fixed, were certain pattern used in a smooth shade was not properly handled
- Imposition: Issue fixed where a page scaling factor was not properly regarded if JavaScript-based imposition was applied
- To PDF for images:
- Problem solved, where PDF creation resulted in wrong dimension for certain JPEG
- Problem solved, where a certain way of placing text in a SVG resulted in an unexpected result
- Issue fixed, where a CMYK TIFF was not completely converted to PDF
- Problem solved, where transparent regions from CMYK TIFF files became white
- Problem solved, where 8bit CMYK TIFF files with Photoshop alpha layers were not converted to PDF correctly
- Issue fixed, where conversion from TIFF with a smaller BBox than Path-to-clip resulted in a thin white line
- Issue fixed, where conversion of certain high-resolution TIFF resulted in a slightly shifted result
- Issue fixed, where a multichannel TIFF could not be properly converted to PDF
- Problem solved, where a TIFF using the deprecated "Old-style JPEG (in TIFF)" compression could not be converted
- Issue fixed, where an uncompressed grayscale TIFF using 8-Bit could not be converted properly
- Issue fixed, where conversion of a certain TIFF using 16-Bit resulted in gray tiles
- Issue fixed, where a CMYK TIFF using 8-Bit with JPEG compression was converted correctly
- Problem solved, where a TIFF containing an ICC profile with issues could not be converted
- Issue fixed, where a TIFF with Photoshop alpha layers exceeding the dimension of the image itself was not handled properly
- Problem solved, where the dimension of a certain JPG image using a resolution with decimal values was not properly maintained
- To PDF: Problem solved, where a certain type of scaling in a CF2 file was not properly interpreted
- ZUGFeRD: Issue solved, where XMP entry for Version was set to "1p0" instead of "1.0"
- Reports
- XML/JSON: Explicit reporting of default color spaces
- JSON v2: Issue fixed, where no report was generated for password protected PDFs
- JSON v2: Issue fixed, where no report was generated for PDFs with an invalid colorspace type for an image mask
- JSON v2: Issue fixed, where embedded files with AF entry were not listed
- XML: XML schema (XSD) adjusted to cover output_intents entries
- Server
- Issue fixed, where a specified limitation of parallel processes was internally always set to 8 processes even the License Server was used
- CLI
- To PDF: Problem solved, where PostScript-to-PDF conversion could result in unnecessary high memory consumption
- Profile execution: Optimized handling for hits per document if no report option is selected in order to increase performance
- Distributed processing
- Problem solved, where result files of Actions using sub-folders were not transferred back to the Client
- Problem solved, where placing PDFs using the "Place content on page" Fixup was not properly done
- General
- Actions in ProcessPlan: Issue fixed, where a defined sub-folder structure was not regarded
- Process plans: A "File pick up" step now restores the original file name as well
- Process plans: Problem solved, where a combination of "Rename PDF" and "Do not save modified input file" resulted in an error
- Issue fixed, where a Process plan execution was not successful with the first runs but was successful later
- Problem solved, where Profile execution was not successful if certain Fixups were using certain settings
13.2.388
- A free of charge update of pdfaPilot 13 Desktop for owners of a pdfaPilot 13 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Features
- New Properties
- Glyph without contour used for non white space character
- Enhanced Properties
- All barcode-related Checks: Revised and optimized analysis for improved recognition and higher speed
- Report PDF syntax issues: Reporting for invalid end-of-data (EOD) marker in inline images
- Desktop
- Password visibility can be toggled
- Process plans: Multiple steps can now be marked as a group and activated or deactivated together and assigned a variable
- Actions
- Visualizer: Support for RGBA (RGB with transparency) and GrayA (Gray with transparency) as output colorspace for PNG
- Save as image: Support for CMYK + Alpha (CMYK with transparency) for TIFF
- Visualizer: Support for RGBA (RGB with transparency) and GrayA (Gray with transparency) as output colorspace for PNG
- Most recent version of Adobe PDF Library integrated (v18.0.5PlusP1c)
Fixes
- Desktop
- Acrobat Plug-in: Problem solved, where other 3rd-party Plug-ins could not be closed anymore when a PDF was processed by pdfToolbox
- Batch processing: Processing result in crashing application if "Do not save modified input file" was enabled
- Explore PDF: Problem solved, where analysis was not successful if certain data after EOF marker existed
- Explore PDF: Problem solved, where certain PDF with content stream issues was not analyzed properly
- Layer explorer: Issue fixed, where the visibility of cascading layer groups could not be switched on or off properly
- PDF Standards
- Convert to PDF/A-...: Problem solved, where in rare cases a date mismatch between Document Info and XMP Metadata was not adjusted
- Fixups
- Convert TrueType fonts to CFF (for font not matching PDF/A-2 requirements): Issue fixed, where the result PDF had certain font issues
- Create
invisible text via OCR: Issue fixed, where invisible text was not
positioned properly if MediaBox is larger than CropBox
- Create invisible text via OCR: Issue fixed, where an empty text block was generated although the PDF had no text
- Downsample/recompress
images: Issue fixed, where a destination resolution of "0" was not
handled properly and resulted in a missing image
- General font processing: Issue fixed, where certain, rare supplement encoding entries in CFF fonts were not regarded properly, resulting in a changed visual appearance of a glyph
- Place circle|rectangle: Issue fixed, where created layers did not contain certain entries in the layer order array and therefore were not listed as layers in certain PDF viewers
- Remove
annotations: Problem solved, where processing resulted in an error due
to certain, incomplete annotation entries
- Remove pages: Issue fixed, where page labels were not properly restored when pages were deleted
- Scale
pages: Problem solved, where "Fit from outside (cut page)" didn't
reduce the size of TrimBox and BleedBox when needed
- Set layer default to ON/OFF: Problem solved where processing was not executed properly
- Subset fonts: Issue fixed, where processing could change the visual appearance of a particular glyph in a certain case
- All rendering-based Fixups: Improved error message when required memory size could not be allocated
- Checks
- Character code can not be mapped to Unicode: Issue fixed, where certain CMap entries were not properly taken into account
- Find barcodes:
- Issue fixed, where barcode recognition took quite long on certain large pages
- Problem solved, where an unnecessary high amount of memory was used (Linux only)
- Improved recognition of certain, low quality scanned barcodes
- Issue fixed, where an inverted barcode could not be found in certain cases
- Annotation inside BleedBox/TrimBox Problem solved, where annotations were not detected correctly in some cases
- Actions
- E-mail to PDF: Issue solved, where certain tables were not properly formatted [CA1033322]
- ToPDF:
- Problem solved, where the resolution of JPEG images was not maintained in certain cases
- Issue fixed, where MS Publisher files were not converted by MS Office but via LibreOffice
- Issue fixed, where a TIFF using "Old-style JPEG (in TIFF)" compression could not be converted
- E-invoice (ZUGFeRD): Problem solved, where XML schema for validation could not be found if the executable was called from a network path
- Reports
- XML: Issue fixed, where the report contained for a PDF with an embedded file was incomplete
- XML: Schema (XSD) adapted, as certain entries were not clearly defined
- Server
- Job view: Problem solved, where starting or stopping a job did not maintain the scrolling position
- Job view: Problem solved, where starting or stopping a job did not maintain the scrolling position
- CLI
- Several Fixups will now report a more detailed error message if an invalid RegEx is used
- Problem solved, where processing failed due to missing dependencies in certain RHEL (and SLES) based Linux distributions [e.g. an AlmaLinux docker environment]
- General
- Native ARM support for installer on macOS
- RegEx used in Checks and Fixups: Problem solved, where certain incorrect RegEx syntax was not reported properly during execution
- Adjusted version info in "info.plist" to match specified scheme by Apple (macOS only)
- Rendering: Problem solved, where certain colored PDFs were displayed as gray, caused by a specific RGB-ICC profile as transparency blend color space
- Rendering: Issue fixed, where certain, slightly corrupt PDF could no longer be rendered
- "ZuGFeRD" renamed to "e-invoice"
13.2.388.1
- A free of charge update of pdfaPilot 13 Desktop for owners of a pdfaPilot 13 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Fixes
- Process plans:
- Data loss problem fixed that could occur when Process Plans with File Pickup in combination with “Do not save modified input file” were used
14.0.392
- An upgrade to pdfaPilot Server 14, pdfaPilot CLI 14 or pdfaPilot SDK 16 from earlier versions of these products requires a Software Maintenance Agreement (SMA). Please contact your reseller for further information.
Features
Desktop
- Space usage dialogue
- Edit Checks: New "Mouse selector" to define a custom area
- Edit Fixups: New "Mouse selector" to define a custom area
- Library Manager: Support for exporting multiple libraries simultaneously
- Layer explorer: Usability improvements, e.g. "Add missing layer"
- Variables editor: Insert JavaScript allows for importing JavaScript versions of Checks or Fixups
- Variables editor: Predefined sample Runlist imposition objects added
- Profile summary: Overview can be exported as CSV
Process plans
- Editor: Process plans can have annotations
- "Process plan" step: Option to process only certain pages
- "Process plan" step: Process pages individually in a loop
- Create PDF file copy: Option "Copy into variable" to save the path of the created PDF for later use
- Action "Image export": Support for Lab color space for TIFF images
- Action "Split and reorder": Option "Digits for page number"
- Action "Image export": Option "Digits for page number"
- "Add files" step: Option to replace current PDF with another file referenced by a path
- Improved highlighting for steps connected by "File pick up" and "Compare" steps
- Action "Imposition": Results are available in "app.doc.result" for subsequent use via JavaScript
New Fixups
- Place file on path
- Derive stroked from filled vector path
- Replace barcode
- Adjust Form XObject BBoxes to CropBox
- Remove data: Removes data such as annotations, metadata or private data
Enhanced Fixups
- Convert colors: Optimized processing of multipage PDFs and multiple referenced objects
- Convert page content into image: Support for Lab color space
- Flatten transparency: Filter to exclude objects from flattening
- Place barcode: New option to define the background color of a placed barcode
- Place barcode: New section for advanced settings to define additional barcode generation parameters (JSON)
- Place barcode|text|content: Improved reporting when processing results in an error, e.g. due to invalid barcode values or JavaScript issues
- Arbitrary JavaScript-controlled Fixups: Automatic fallback to default values if parameters are missing
New Properties
- Size of document XMP
- Size of object XMP (on page level)
- TrimBox is landscape
- TrimBox is portrait
Enhanced Properties
- Find barcodes: Support for DataBar (RSS 14) codes
- Find barcodes: "Color distance between barcode / matrix code and background” check works better for non-uniform colors
- Operators for text input fields: "is contained in list (ignore upper/lower case)" and "is not contained in list (ignore upper/lower case)"
- Text on page: RegEx capture groups are now reported in trigger values in XML, JSON and JSONv2 reports as well as in JS Variable "app.doc.result" objects
- Various properties: Added Variable support for units
New or enhanced predefined Profiles and Process plans
- Library: Prepress, Color and Transparency:
- Identify color pages: Returns a hit for every page that contains color and stores the result in variables
- Generate 5mm bleed (autoselect bleed generation method)
- All "GWG 2022 R1"-based Profiles: Improved ink coverage checks and of identifying empty pages
- All "GWG 2015" & "GWG 2022" Profiles removed as they have been deprecated by GWG
New or enhanced predefined Fixups
- Library: Prepress, Color and Transparency:
- Generate 5mm bleed (autoselect bleed generation method)
- Derive spot color for haptic print
- Redraw cut line
New Library: Processing Steps
- Profiles and Process plans:
- Prepare PDF using technical colors with Processing Steps layers
- Add Processing Steps layers
- Verify compliance with Processing Steps (ISO 19593-1) for packaging and label (formerly part of the "PDF Standards" Library)
- List Processing Steps metadata information (formerly part of the "PDF Standards" Library)
- Fixups
- Flatten transparency, keep Processing Steps layers
- Checks
- Is Processing Steps layer
New or enhanced Actions
- Create file
- Imposition: The "place content" functionality is now available in JavaScript-based impose scripts.
- ToPDF: Support for HEIF and HEIC images
- SaveAsImage: Support for Lab color space for TIFF images
New or enhanced Quick Fix
- Apply 2D transformation matrix to page content: Allows scaling, rotation, translation and skewing of content
Most recent version of Adobe PDF Library integrated (v18.0.5PlusP1g)
- Most recent version of Adobe PDF Converter integrated (PostScript to PDF conversion; v3.2.0Plus1m)
- Internal HTML converter updated to callas pdfChip (v2.6.096)
Fixes
Desktop
- Workspace: Problem solved, where Process plan setting "Do not save modified input file" was not respected
Process plans
- Reports: Issue fixed, where a Variable defined for the PDF overview report template was not respected
- Do not save modified input file: Problem solved, where files were not handled properly if loops existed in the Process plan
Fixups
- Convert colors: Problem solved, where processing time increased due to non-optimal handling of shared resources
- Convert page content into image: Improved handling of existing Output Intents for rendering if object filters are used
- Convert page content into image: Improved handling of existing Output Intent when objects were excluded from bleed creation to ensure correct color values
- Crop pages: Problem solved, where certain, unnecessary content stream operators were not handled properly and resulted in shifted content
- Make document XMP Metadata compliant: Problem solved, where processing resulted in a failure
- Optimize the PDF for fast web view: Issue fixed, where execution was not reported
- Place content on page: JavaScript errors are now reported if a failure occurs due to this error
- Place file on page: New options to specify width and height for placed file
- Remove invisible image data: Problem solved, where image visually disappeared due to a specific SoftMask usage
- Remove objects: Problem solved, where Form XObjects used for bleed remained outside page area
- Set layer initial print state: Problem fixed, where initial state could not be set to "Never prints" in certain case
- Place ... based Fixups: Issue fixed, where only one Fixup was reported, when several Fixups were executed
- Subset fonts: Problem solved, where certain supplement encodings were not handled correctly, resulting in incomplete rendering with certain viewers [FP80291]
- General font processing: Problem solved, where a double SPACE was inserted, although not necessary
- General font processing: Problem solved, where unnecessary entries in the encoding of a CFF font caused problems on certain output devices
Checks
- Is landscape: Changed behavior, now uses the CropBox to determine orientation (was BleedBox before)
- Is portrait: Changed behavior, now uses the CropBox to determine orientation (was BleedBox before)
- Image is not valid: Problem solved, where analysis could not be executed properly
- Find barcodes: Problem solved, where size of found "RSS Extended Stacked" barcodes was not determined correctly
- Find barcodes: Issue fixed, where a barcode was reported for a layer, although not assigned to this layer
- Sifter-based properties: Issue fixed, where certain clipped smooth shades were incorrectly interpreted
- General font analysis: Problem solved, where a certain unusually high value in Font CMaps resulted in unnecessary long processing and memory consumption
Process plans
- Action "Split and reorder": Issue fixed, where output filename was indexed instead of being derived from the page number
Actions
- ToPDF:
- Images: Issue fixed, where certain Tiff files could not be converted to PDF
- PostScript:
- Problem solved, where clippings were not handled correctly in some cases
- Problem solved, where content was not handled properly when certain PostScript constructions were used
- Issue fixed, where not all page geometry boxes were retained after conversion
- Extract images: Problem solved, where certain images were inverted when exported
- Extract content: Problem fixed where certain combined UTF-16 code (to represent a UTF-32 character) was not handled correctly (Linux only)
- SaveAsImage: Problem solved, where rendering could not be performed correctly for certain file dimensions at certain resolutions
- SaveAsImage: Issue fixed, where exported multichannel TIFF files were inverted when created with high resolution
Reports
- XML: Problem solved, where report creation failed in a certain case
- XML: Schema (XSD) adapted, as certain entries were not clearly defined
General
- Problem solved, were certain corrupt metadata could result in an unstable behavior
- JavaScript Variables: Problem solved, where accessing invalid data could result in unstable behavior in certain cases
System requirements
- Mac: macOS version 10.15 or newer, 64-bit-compliant
14.1.395
- A free of charge update of pdfaPilot 14 Desktop for owners of a pdfaPilot 14 Desktop license
- A free of charge update of pdfaPilot Server, pdfaPilot CLI or pdfaPilot SDK for owners of a Software Maintenance Agreement (SMA)
Features
Desktop
- Testmode: A new "Cancel" button next to the progress bar, makes it easier to cancel the run when it takes too long, while keeping the Check results collected so far
- ProcessPlan editor: Improved "snap to grid" functionality for steps and annotations
- *ProcessPlan editor: Annotations now support different text alignment options
Fixups
- Remove invisible image data: New option "Duplicate multiple used images if necessary"
Actions
- MergePDF: Pagelabels of input files will now be maintained
- Internal HTML converter updated to callas pdfChip (v2.6.098)
Fixes
Desktop
- Object Inspector: Problem solved, where the position of an object was not properly transferred to the derived Check
- Search Libraries dialog: Fixed an issue, where entries in the Libraries popup were not sorted alphabetically
New Fixups
- Remove broken link annotations and bookmarks
New Properties
- Link annotation uses broken destination
- Bookmark uses broken destination
Enhanced Profiles
- Library: PDF Standards:
- Convert to PDF/X-1...: "Recompress JPEG2000 images as JPEG" has been added as an additional default Fixup
Fixups
- Add missing layer / Put objects on layer: Issue fixed, where created layer structure contained an empty group entry
- Convert TrueType to CFF: Problem solved, where glyphs were not properly handled due to some rare encoding entries
- Create invisible text via OCR: Issue fixed, where text was created with an offset if the boxes were not properly nested
- Downsample/compress bitmap images: Problem solved, where certain CCITT-decoded inline images were not converted properly
- Place rectangle: Problem solved, where the position differed if the rounded corner value was set
- Remove from layer: Problem solved, where certain layer structures where not properly maintained and objects could become invisible
- Remove XMP metadata: Problem solved, where not all defined metadata was removed when multiple Fixup settings were defined
- Remove XMP metadata: Issue fixed, where processing resulted in an error when "Set Title entry to filename" was executed in the same Profile
- Subset fonts: Problem solved, where certain CID encoding for space characters could result in glyphs vanishing
- General font processing: Problem solved, where certain, corrupt cmap structures were not properly detected or repaired
Checks
- Find barcodes:
- Issue fixed, where the number of barcodes found varied from run to run in certain cases (Windows only)
- Improved recognition of QR code quiet zones when the surrounding background is just slightly different to the background of the barcode area
- Improved barcode detection and more accurate dimension calculation
- Font is not valid: Improved recognition of certain font issues where glyphs were not listed correctly in the necessary tables
Actions
- Extract XMP metadata: Issue fixed, where images in Form XObjects with no dimensions were not handled properly
- Modify Structures: Problem solved, where bookmarks using the "Open" state were not inserted correctly
- To PDF: Problem solved, where certain 16-bit TIFF images could not be converted to PDF properly
- To PDF: Problem solved where temporary, internal files being created during conversion to PDF were not being deleted even though the final PDF was saved
CLI
- Problem solved, where placing content failed due to a missing "libatomic1" package in certain, Linux distributions
- Merge PDF: Issue fixed, where attempting to merge a corrupt file resulted in an incomplete merge instead of triggering an error
General
- Profile processing: Discontinued creation of dedicated log files in the TEMP folder of the application if processing errors occur
- Improved recognition and repair of certain invalid SMask definitions
- Problem solved, where internal content stream optimization did not set the color space for used SoftMasks not correctly in some cases, which could result in display issues
- Process plans: Problem solved, where temporary files that were marked for deletion after processing were still listed as created files in the output
- Process plans: Problem solved, where requesting an XML report including ink coverage for a step resulted in an error upon execution
- Problem solved, where the application became unstable when OpenCV system libraries were installed on the same system (macOS only)